DS701 Session 3 — Mon Sep 14, 2026
State the four properties a function \(d(x, y)\) must satisfy to be called a metric. Then say, in one line, how a norm \(p(\cdot)\) gives you a metric for free.
Answer:
Every norm induces a metric: \(d(\mathbf{x}, \mathbf{y}) = p(\mathbf{x} - \mathbf{y})\). \(\ell_2 \to\) Euclidean, \(\ell_1 \to\) Manhattan, \(\ell_\infty \to\) Chebyshev. The converse fails: the discrete metric (\(0\) if equal, else \(1\)) comes from no norm.
Let \(\mathbf{u} = [1, 2, 0]\) and \(\mathbf{v} = [3, -1, 4]\).
Compute
Then explain in one sentence why the cosine can be near one while the vectors are far apart in every \(\ell_p\) distance.*
Answer:
Cosine measures direction only — rescale either vector and it does not move. An \(\ell_p\) distance measures the length of the difference vector, so magnitude matters. Nearly parallel and far apart is perfectly consistent.
Two situations from the lecture.
What is the Hamming distance in each case, why does that ranking feel wrong, and which measure from the lecture fixes it (give its formula)?*
Answer: Hamming \(= \ell_1\) on bit vectors \(=\) size of the set difference: Case 1 \(= 10\), Case 2 \(= 5\). So Hamming calls the near-identical long documents more different than two documents that share nothing — it counts raw disagreements without normalizing by how much there was to agree on.
Jaccard fixes it: \[ J_{sim}(x, y) = \frac{|x \cap y|}{|x \cup y|} \qquad \approx 1 \text{ in Case 1},\quad 0 \text{ in Case 2}. \] \(1 - J_{sim}\) is a genuine metric. Lesson: the right distance depends on what the data represents.
Everything today lives in \(\mathbb{R}^d\): a data object is a vector \(\mathbf{x} = [x_1, \dots, x_d]\), a dataset is an \(m \times d\) matrix (rows = objects, columns = features).
Inner product — elementwise multiply, then sum: \[\mathbf{u}\cdot\mathbf{v} = \mathbf{u}^T\mathbf{v} = \sum_i u_i v_i\]
Norm — a length. The \(\ell_2\) norm is the one you know: \[\Vert\mathbf{v}\Vert_2 = \sqrt{\mathbf{v}\cdot\mathbf{v}} = \sqrt{\textstyle\sum_i v_i^2}\]
Distance — the norm of the difference: \[d(\mathbf{u},\mathbf{v}) = \Vert\mathbf{u} - \mathbf{v}\Vert\]
Cosine of Angle — inner product with the lengths divided out: \[\cos\theta = \frac{\mathbf{u}\cdot\mathbf{v}}{\Vert\mathbf{u}\Vert_2\,\Vert\mathbf{v}\Vert_2}\]
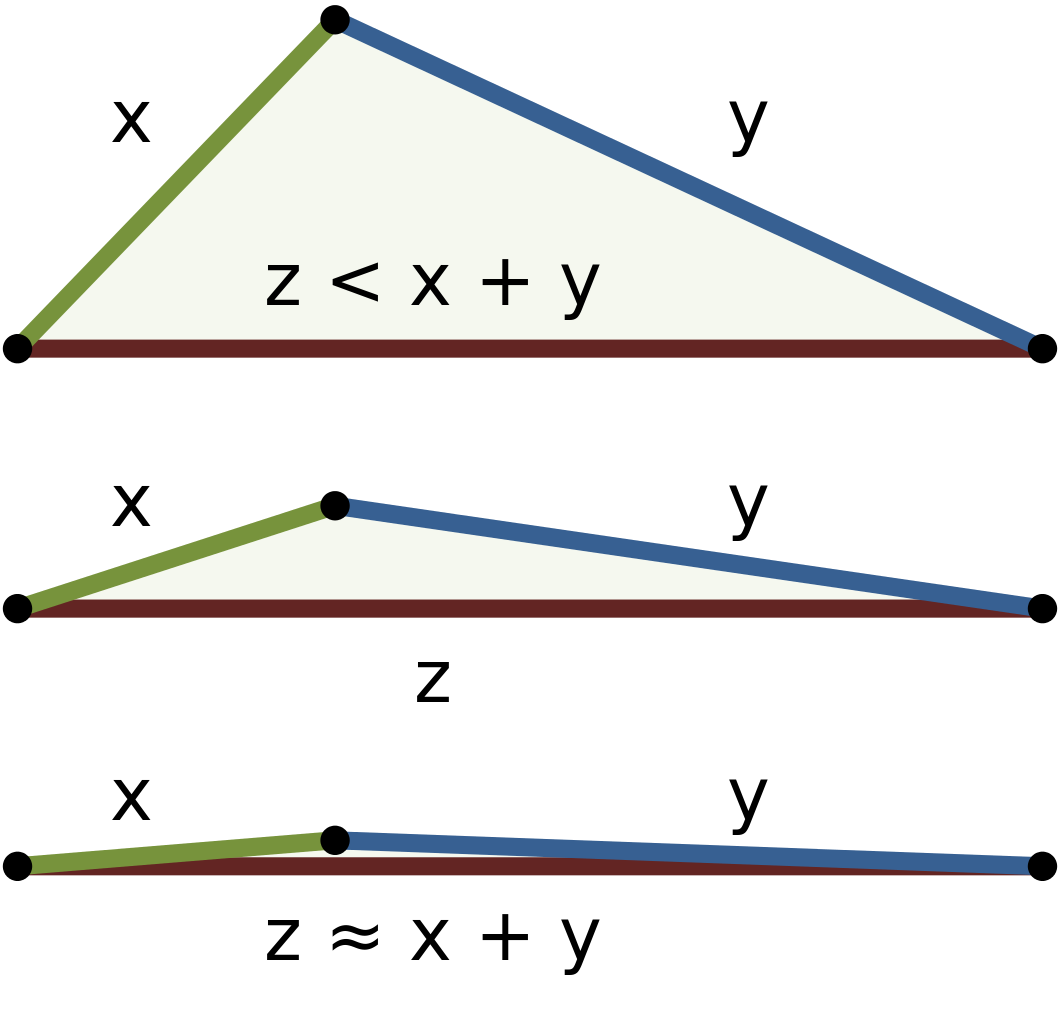
A metric \(d(x,y)\) satisfies

A metric measures dissimilarity: bigger \(=\) more different. On vectors we call it a distance. Symmetry and the triangle inequality are what let us reason about “neighborhoods” — nearest-neighbor search, clustering, and everything downstream leans on them.
Not everything we call a “distance” is one: \(1 - \cos(\mathbf{x},\mathbf{y})\) is not a metric. We will still use it, but we will say dissimilarity.
A norm \(p(\mathbf{v})\): \(p(a\mathbf{v}) = |a|\,p(\mathbf{v})\), \(\ p(\mathbf{u}+\mathbf{v}) \le p(\mathbf{u}) + p(\mathbf{v})\), \(\ p(\mathbf{v}) = 0 \iff \mathbf{v} = 0\).
Every norm gives a metric: \(d(\mathbf{x},\mathbf{y}) = p(\mathbf{x} - \mathbf{y})\).
\[ \Vert \mathbf{x} - \mathbf{y} \Vert_p = \Big(\sum_{i=1}^d |x_i - y_i|^p\Big)^{1/p}, \qquad p \ge 1 \]
| \(p\) | norm | distance |
|---|---|---|
| \(1\) | \(\sum_i \lvert x_i - y_i \rvert\) | Manhattan (Hamming on bits) |
| \(2\) | \(\sqrt{\sum_i (x_i - y_i)^2}\) | Euclidean |
| \(\infty\) | \(\max_i \lvert x_i - y_i \rvert\) | Chebyshev / maximum |
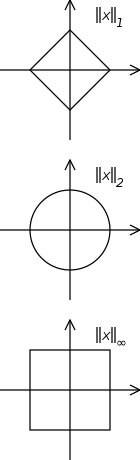
The unit “circles”: diamond \(\subset\) circle \(\subset\) square, because \(\Vert\cdot\Vert_1 \ge \Vert\cdot\Vert_2 \ge \Vert\cdot\Vert_\infty\).
The choice of \(p\) decides what gets emphasized.
\(\ell_1\) — Manhattan
\(\ell_2\) — Euclidean
\(\ell_\infty\) — Chebyshev
Same two points, three different answers: \(A=(3,4)\), \(B=(1,1)\) gives \(5\), \(\sqrt{13}\), \(3\). The ranking of neighbors can change with \(p\) — that is the point, not a nuisance.
Cosine similarity — the angle, lengths divided out: \[ \cos(\mathbf{x},\mathbf{y}) = \frac{\mathbf{x}^T\mathbf{y}}{\Vert\mathbf{x}\Vert\,\Vert\mathbf{y}\Vert} \]
Euclidean distance — the length of the gap: \[ \Vert\mathbf{x} - \mathbf{y}\Vert_2 \]
Word-count vectors: document B \(=\) document A pasted twice. Cosine says identical (\(1\)); Euclidean says far (\(\Vert\mathbf{A}\Vert\)). For text we usually want the proportions, not the length → cosine.
Rule of thumb: ask “do I care about magnitude?” If not, cosine (or normalize to unit length first, after which Euclidean and cosine rank neighbors identically).
The units of each feature are part of the model. Wine dataset, 13 chemical measurements:
| feature | typical range | std. dev. |
|---|---|---|
hue |
0.5 – 1.7 | 0.23 |
alcohol |
11 – 15 | 0.81 |
magnesium |
70 – 160 | 14 |
proline |
280 – 1680 | 314 |
Raw Euclidean distance between two wines \(\approx |\Delta\,\texttt{proline}|\): proline alone carries \(99.7\%\) of the total variance. Twelve features are invisible.
Standardize — per feature, subtract the mean and divide by the standard deviation — and the nearest neighbors change. In the activity you will measure exactly how much (spoiler: 1-NN accuracy on the wine type goes from ~0.65 to ~1.0).
Two separate decisions, both yours: which metric, and which units. Cosine does not rescue you from bad units — the direction is still dominated by the big coordinate.
Bit vector as a code (every position matters): Hamming \(= \ell_1 =\) number of bit flips.
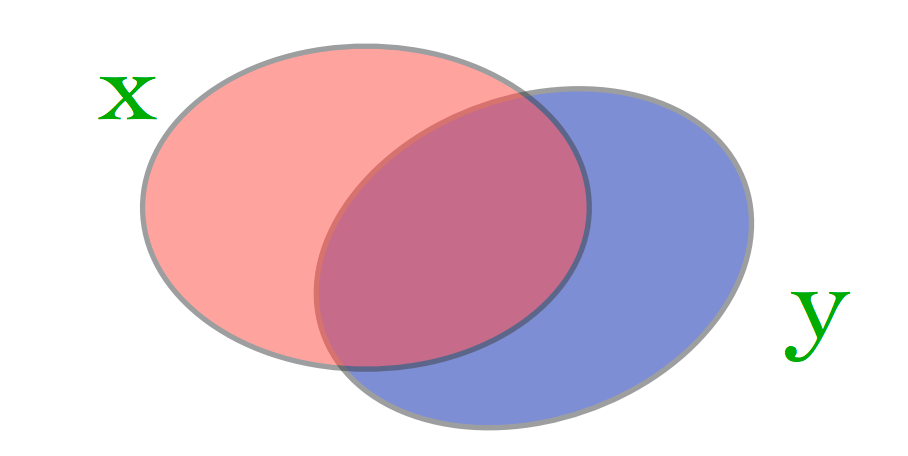
Bit vector as a set (which items are present): Hamming counts the set difference, and that misleads — 10 differing words out of thousands beats 5 disjoint words.
Jaccard normalizes by how much there was to agree on: \[ J_{sim} = \frac{|x \cap y|}{|x \cup y|}, \qquad J_{dist} = 1 - J_{sim} \ \text{ (a metric)} \]
| data | first choice |
|---|---|
| real measurements, comparable units | Euclidean (\(\ell_1\) if outliers) — standardize first |
| word counts, varying lengths | cosine |
| item sets / baskets | Jaccard |
| aligned binary codes | Hamming |
scikit-learnGoal: build Euclidean, Manhattan, cosine and Jaccard distance matrices on real data with numpy, verify them against sklearn / scipy, watch nearest neighbors change with the metric and with feature scaling.
numpy, pandas, matplotlib, scipy, scikit-learn only.The activity notebook goes live on the day of the lecture. Colab is optional — you can also open it on GitHub and run it locally.
Full lecture notes: Distances and Time Series
sklearn fit / transform API: Scikit-Learn appendix