Recap: Dimensionality Reduction — PCA and t-SNE
DS701 Session 16 — Wed Oct 28, 2026
1. PCA in one picture
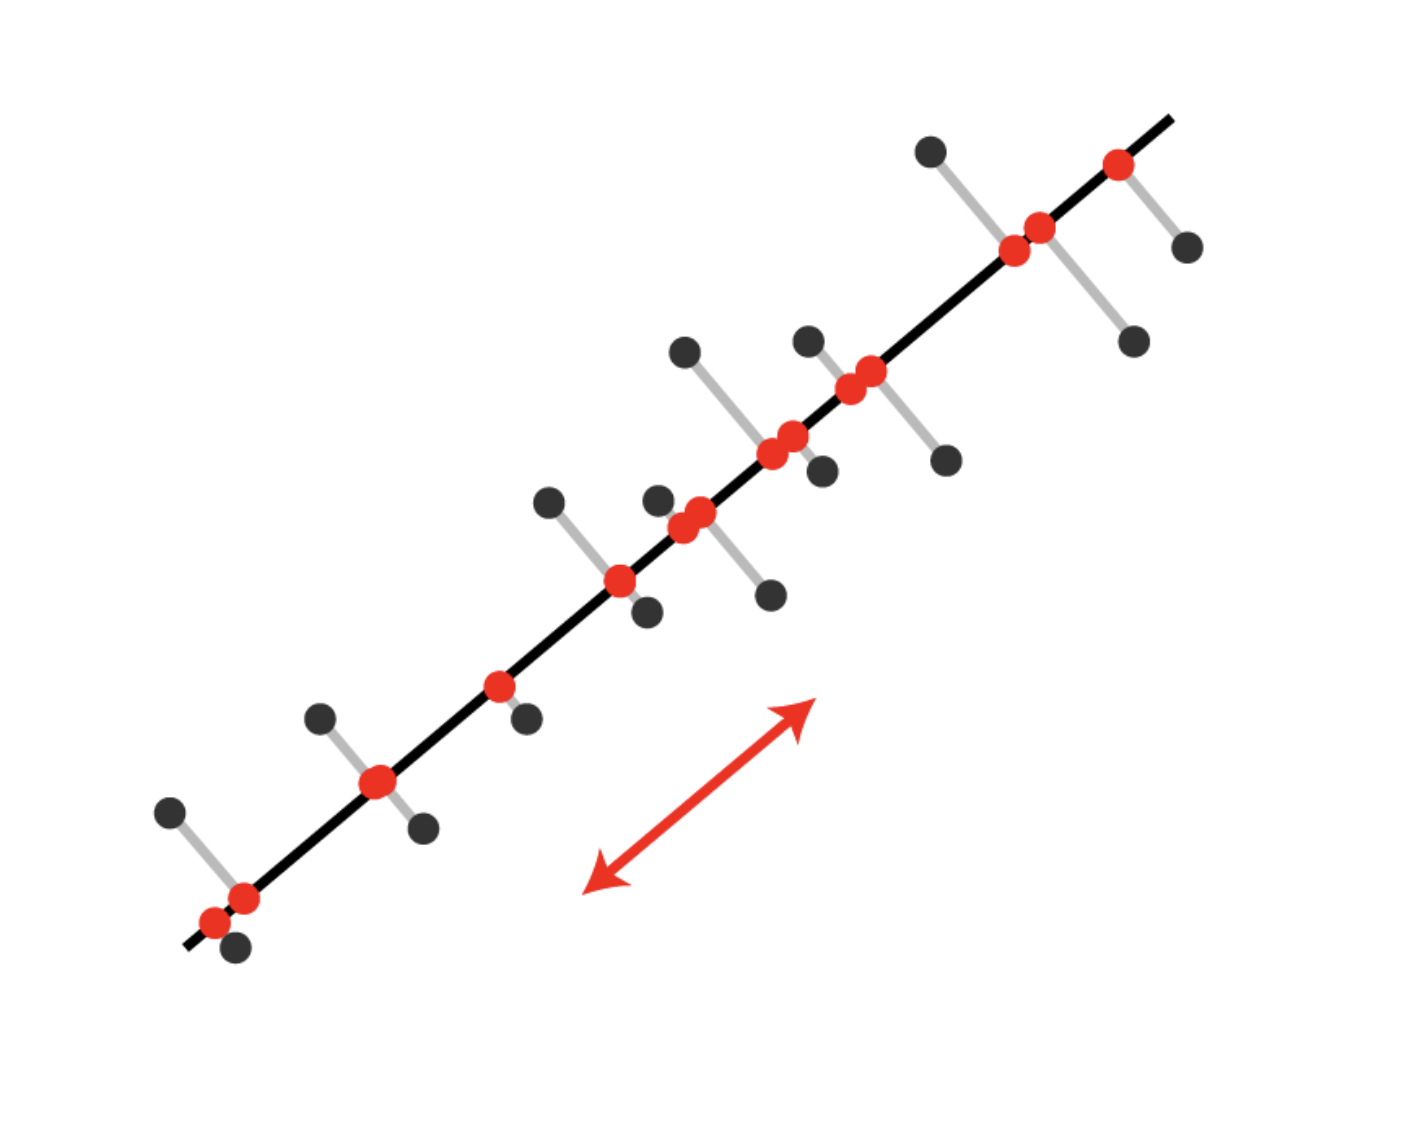
The sum of variances of the projected points is a maximum.
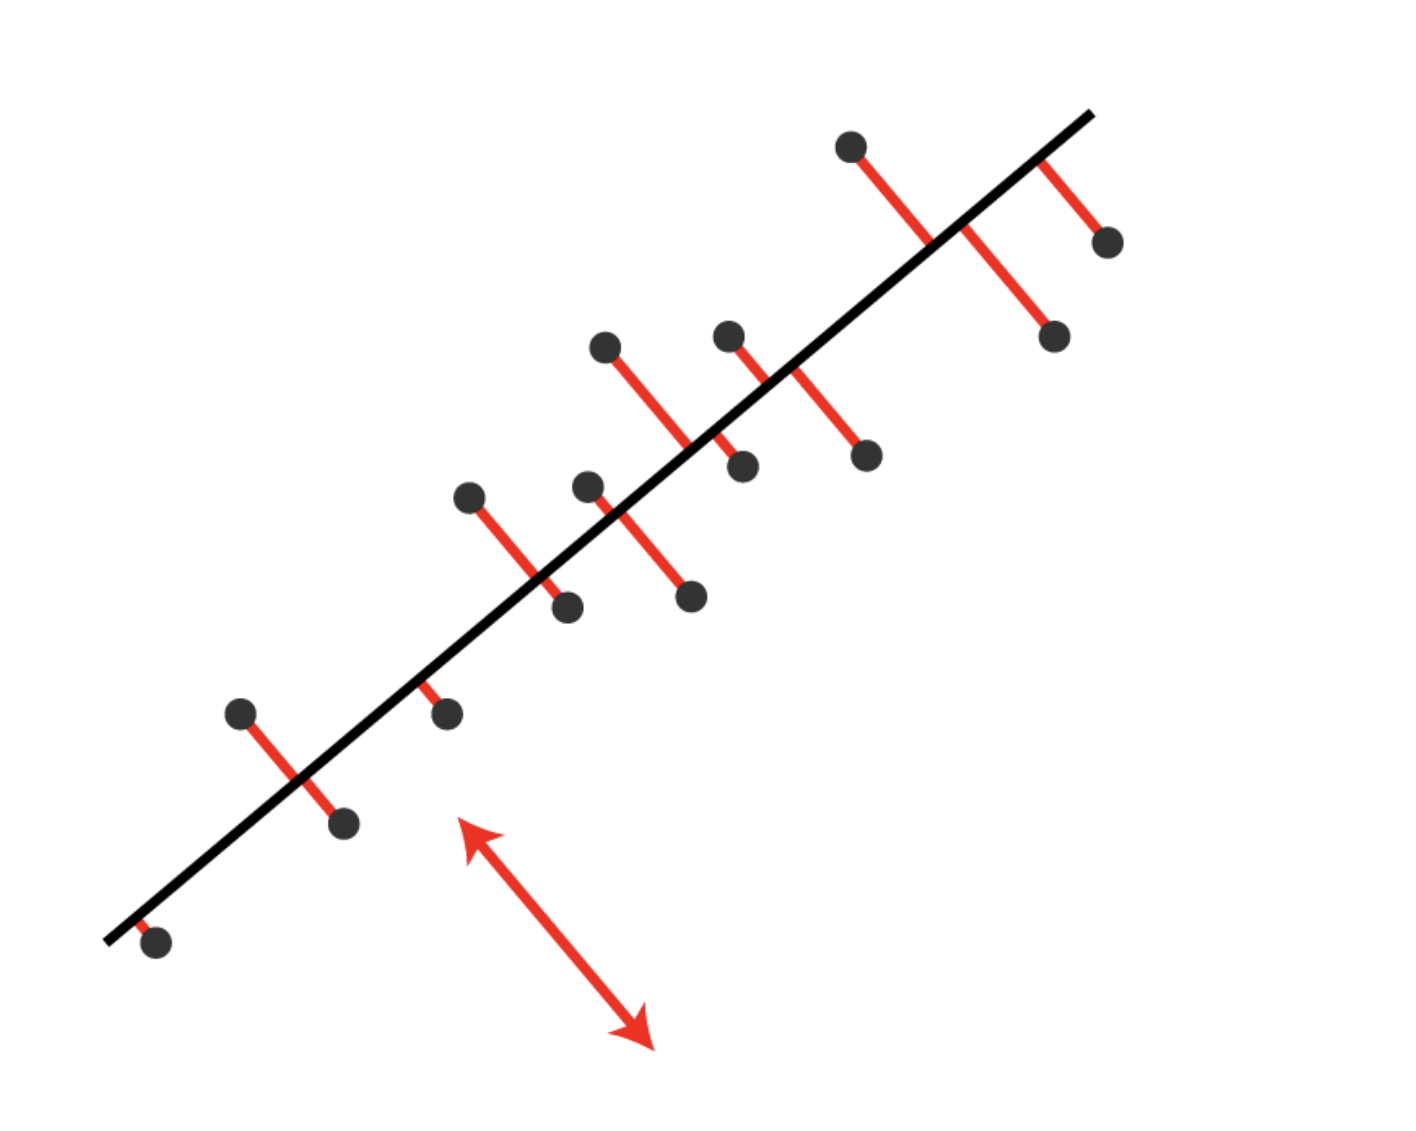
The sum of residuals (squared distances from points to the line) is a minimum.
These are the same optimization: for centered data, projected² + residual² is a fixed total, so maximizing one minimizes the other.
6. To scale or not to scale
Same four people, height in feet vs. centimeters:
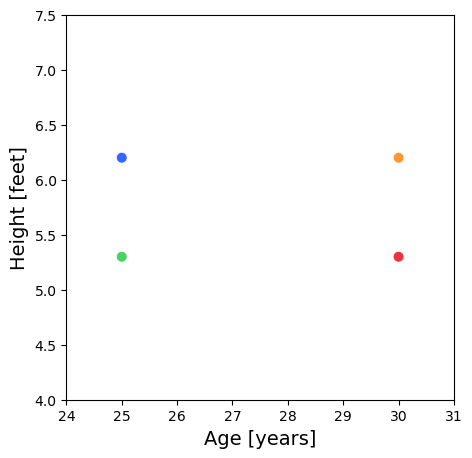
Height in feet — variance runs horizontally (age).
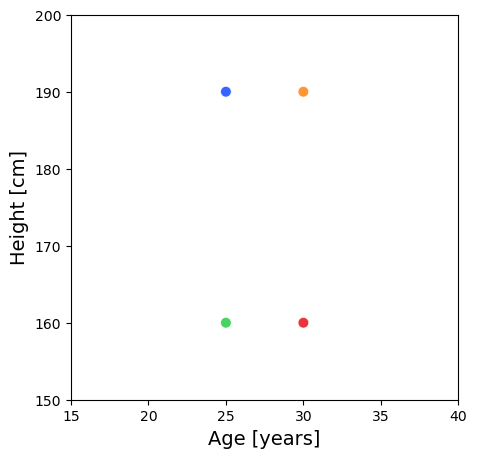
Height in cm — variance now runs vertically.
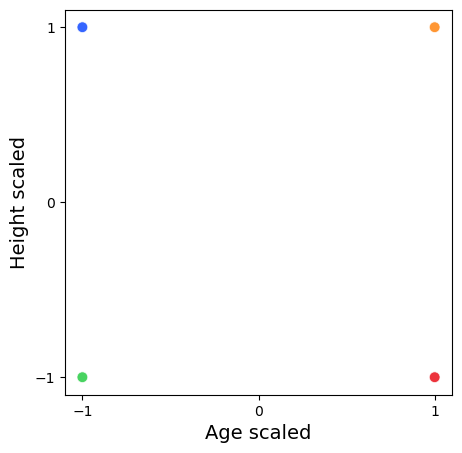
Standardized — variance shared evenly.
Variance is unit-dependent, so PCA is not scale-invariant. Standardizing means you are doing PCA on the correlation matrix — best practice whenever features have different units or scales.
7. Why this matters: genes mirror geography
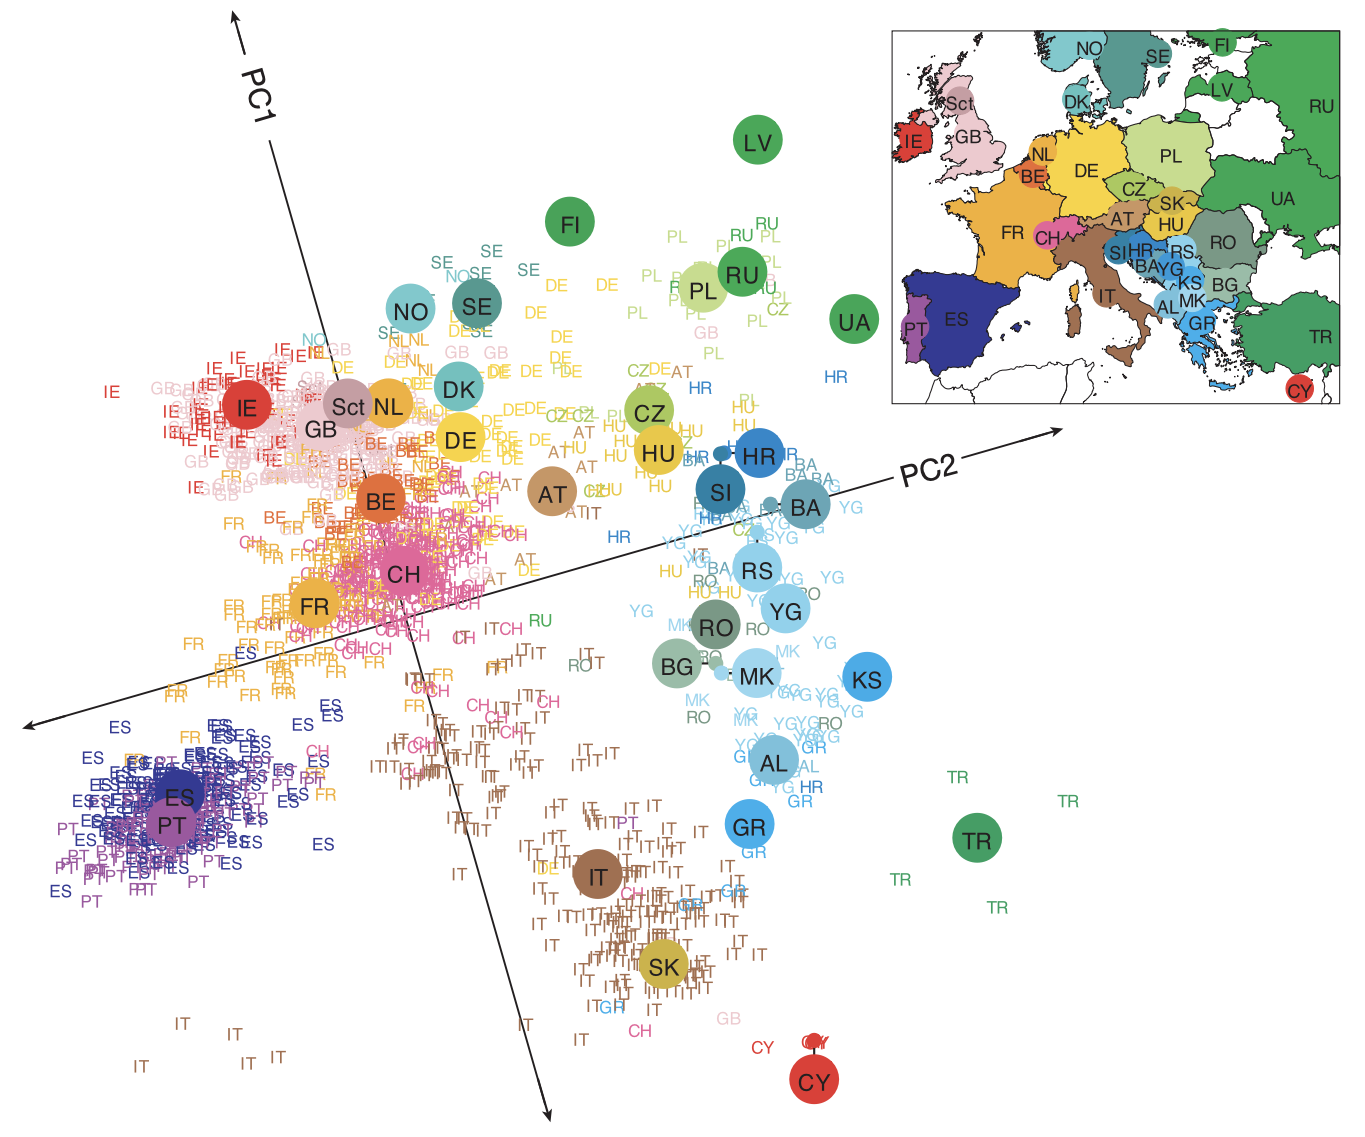
- ~3000 individuals × ~500k SNPs (each entry a 0/1/2 minor-allele count), reduced to two components; the 1387 people with all four grandparents from one country are plotted.
- PC1 and PC2 essentially reconstruct the map of Europe — latitude and longitude fall out of the DNA.
- Two numbers can locate a person’s birthplace to within a few hundred kilometers.
Activity — Case Study 13: Can Thirteen Lab Measurements Tell Wines Apart?
Goal: advise an analytical-chemistry lab that runs a 13-assay panel on every wine lot and has been handed a vendor’s t-SNE plot “proving” the panel separates wines by producer — standardize and run PCA to find how many of the 13 measurements carry the signal, measure what keeping \(d\) of them loses and verify it against the SVD, then write the lab a two-sentence memo and a rule for what the vendor’s plot can and cannot claim.
- Work in groups of 2–3.
- Parts 1–2 are autograded and submitted to Gradescope; the discussion and the memo are participation.
- Finish with the report out: the recommendation and the one caveat for the lab, plus your rule for reading a t-SNE plot — staff will circulate and ask, so agree on your answer.

The activity notebook goes live on the day of the lecture. Colab is optional — you can also open it on GitHub and run it locally.