Linear Regression

Introduction

Introduction

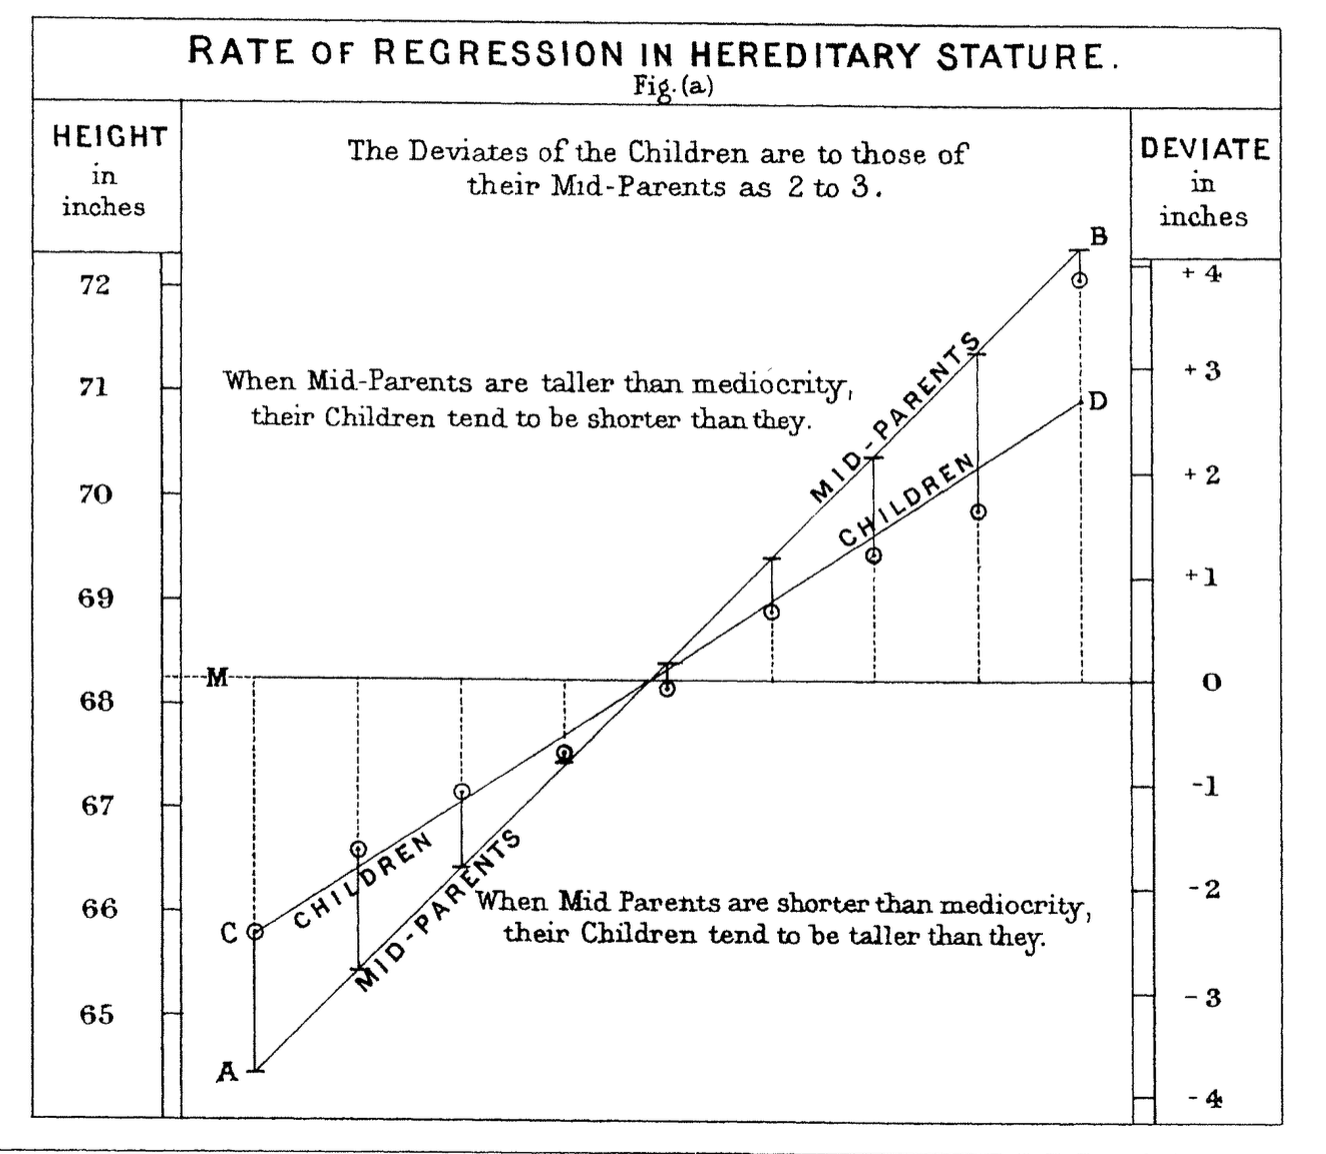
In 1886 Francis Galton published his observations about the height of children compared to their parents.

Regression to the Mean

Defined mid-parent as the average of the heights of the parents.

When parents are taller or shorter than average, their children are more likely to be closer to the average height than their parents.

So called “regression to the mean.”

Galton fit a straight line to this effect, and the fitting of lines or curves to data has come to be called regression as well.

This applies to many situations

“I had so many colds last year, and then I started herbal remedies, and I have much fewer colds this year.”

“My investments were doing quite bad last year, so switched investment managers, and now it is doing much better.”

“The team had a terrible season, so we fired the coach – and this year they’re winning again.”


When in fact, they could be (at least partially) explained by:

Regression to the mean

Model Types

The most common form of machine learning is regression, which means constructing an equation that describes the relationships among variables.

It is a form of supervised learning:

  • whereas classification deals with predicting categorical features (labels or classes),
  • regression deals with predicting continuous features (real values).

Fit to Linear Models

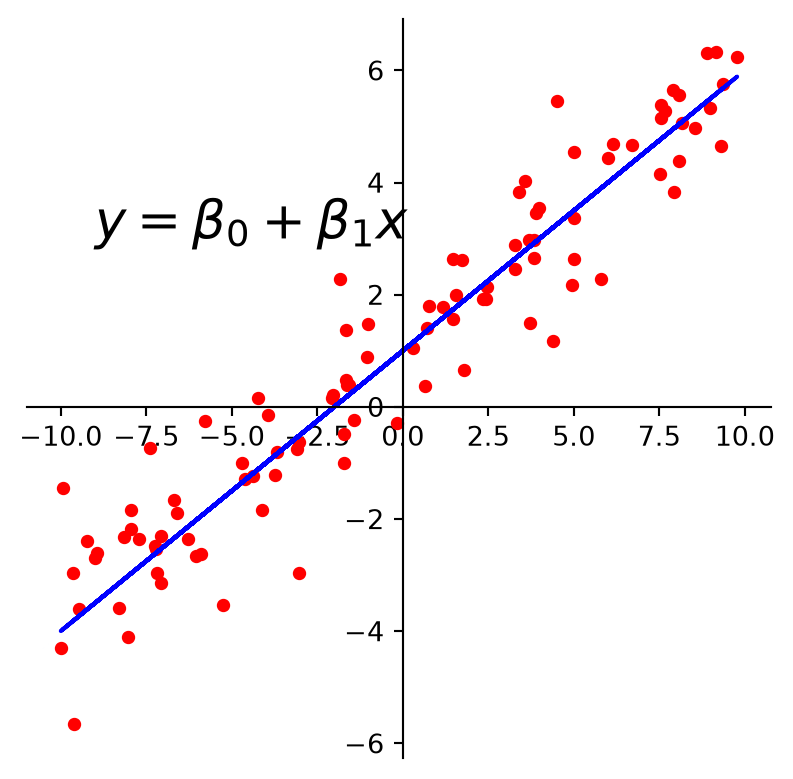
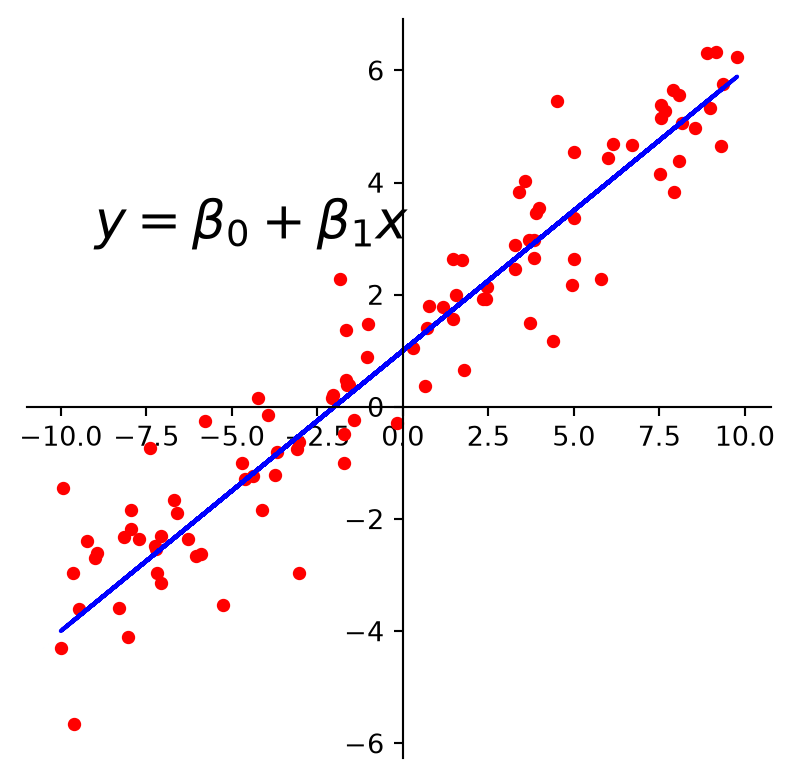
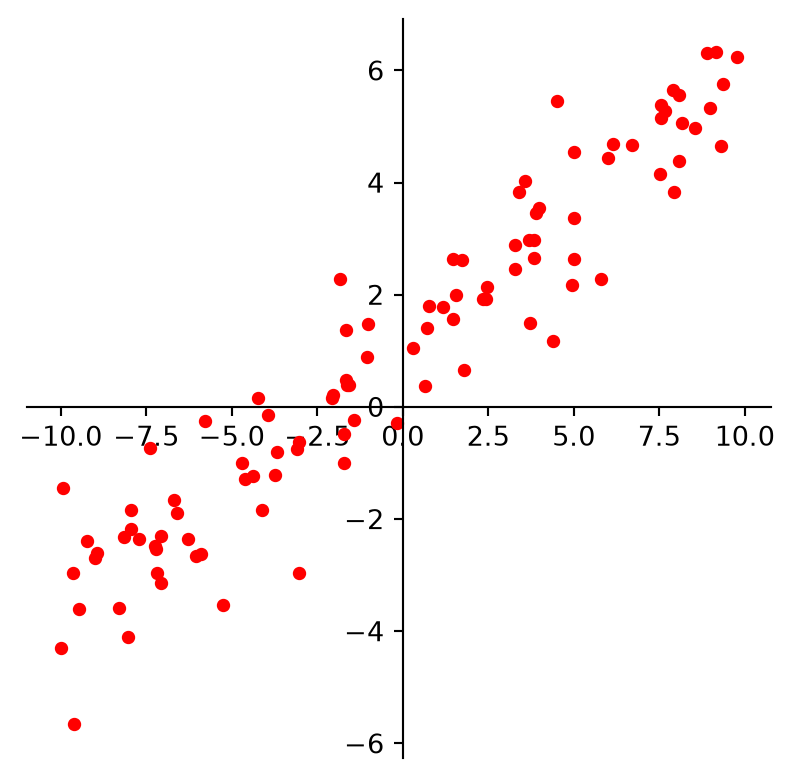
For example, we may look at these points and decide to model them using a line.

Code
ax = plt.figure(figsize = (5, 5)).add_subplot()
centerAxes(ax)
line = np.array([1, 0.5])
np.random.seed(1)
xlin = -10.0 + 20.0 * np.random.random(100)
ylin = line[0] + (line[1] * xlin) + np.random.randn(100)
ax.plot(xlin, ylin, 'ro', markersize = 4)
plt.show()

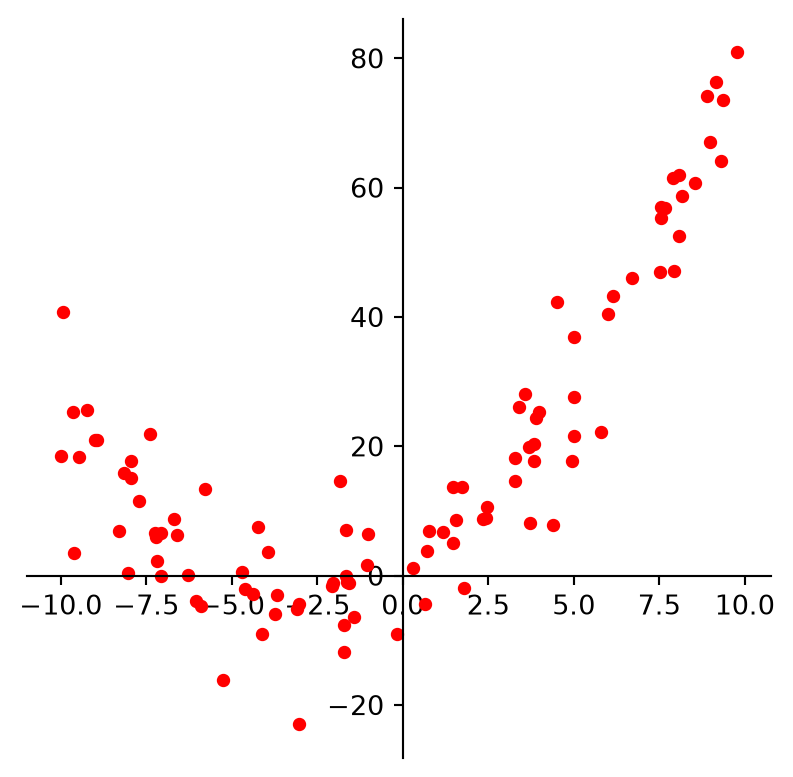
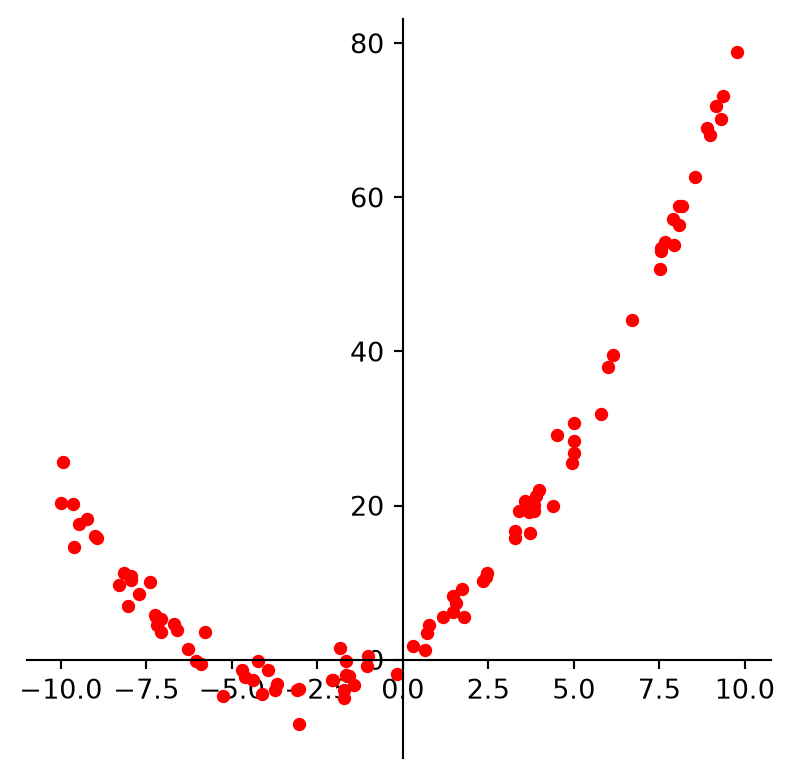
Fit to Quadratic Models

We may look at these points and decide to model them using a quadratic function.

Code
ax = plt.figure(figsize = (5, 5)).add_subplot()
centerAxes(ax)
quad = np.array([1, 3, 0.5])
std = 8.0
np.random.seed(1)
xquad = -10.0 + 20.0 * np.random.random(100)
yquad = quad[0] + (quad[1] * xquad) + (quad[2] * xquad * xquad) + std * np.random.randn(100)
ax.plot(xquad, yquad, 'ro', markersize = 4)
plt.show()

Fit to Logarithmic Models

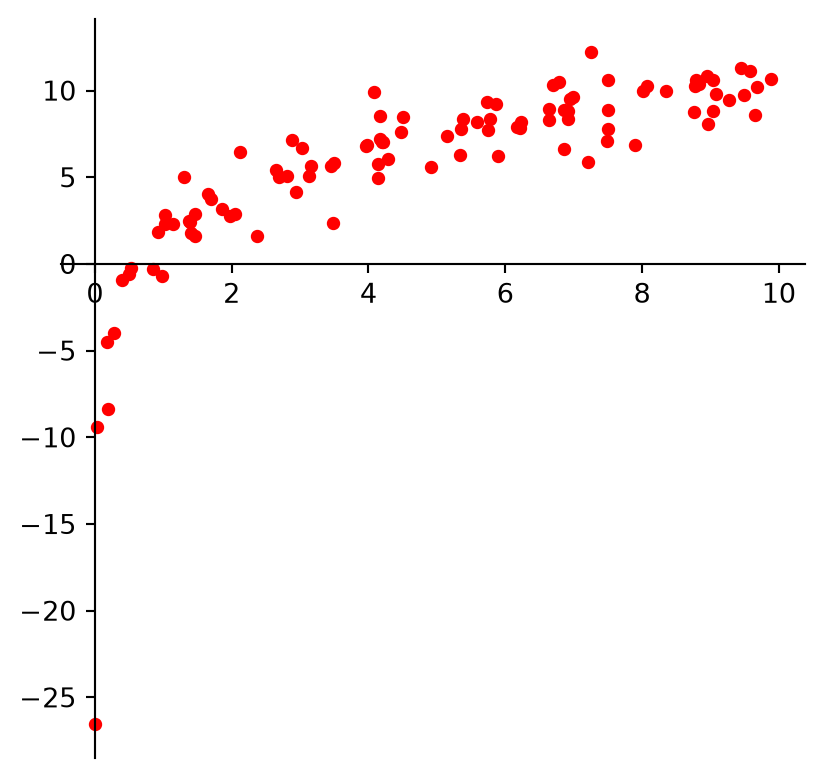
And we may look at these points and decide to model them using a logarithmic function.

Code
ax = plt.figure(figsize = (5, 5)).add_subplot()
centerAxes(ax)
log = np.array([1, 4])  
std = 1.5
np.random.seed(1)
xlog = 10.0 * np.random.random(100)
ylog = log[0] + log[1] * np.log(xlog) + std * np.random.randn(100)
ax.plot(xlog, ylog, 'ro', markersize=4)
plt.show()

Approach

Clearly, none of these datasets agrees perfectly with the proposed model.

So the question arises:

How do we find the best linear function (or quadratic function, or logarithmic function) given the data?

Framework

Framework

This problem has been studied extensively in the field of statistics.

Certain terminology is used:

  • Some values are referred to as “independent,” and
  • Some values are referred to as “dependent.”

Framework cont.

The basic regression task is:

  • given a set of independent variables
  • and the associated dependent variables,
  • estimate the parameters of a model (such as a line, parabola, etc) that describes how the dependent variables are related to the independent variables.

Framework cont.


The independent variables are collected into a matrix \(X,\) sometimes called the design matrix.

The dependent variables are collected into an observation vector \(\mathbf{y}.\)

The parameters of the model (for any kind of model) are collected into a parameter vector \(\boldsymbol\beta.\)

Code
ax = plt.figure(figsize = (5, 5)).add_subplot()
centerAxes(ax)
line = np.array([1, 0.5])
np.random.seed(1)
xlin = -10.0 + 20.0 * np.random.random(100)
ylin = line[0] + (line[1] * xlin) + np.random.randn(100)
ax.plot(xlin, ylin, 'ro', markersize = 4)
ax.plot(xlin, line[0] + line[1] * xlin, 'b-')
plt.text(-9, 3, r'$y = \beta_0 + \beta_1x$', size=20)
plt.show()

Least-Squares Lines

  • The first kind of model we’ll study is a linear equation, \(y = \beta_0 + \beta_1 x.\)

  • Experimental data often produce points \((x_1, y_1), \dots, (x_n, y_n)\) that seem to lie close to a line.

  • We want to determine the parameters \(\beta_0, \beta_1\) that define a line that is as “close” to the points as possible.

Least-Squares Lines cont.

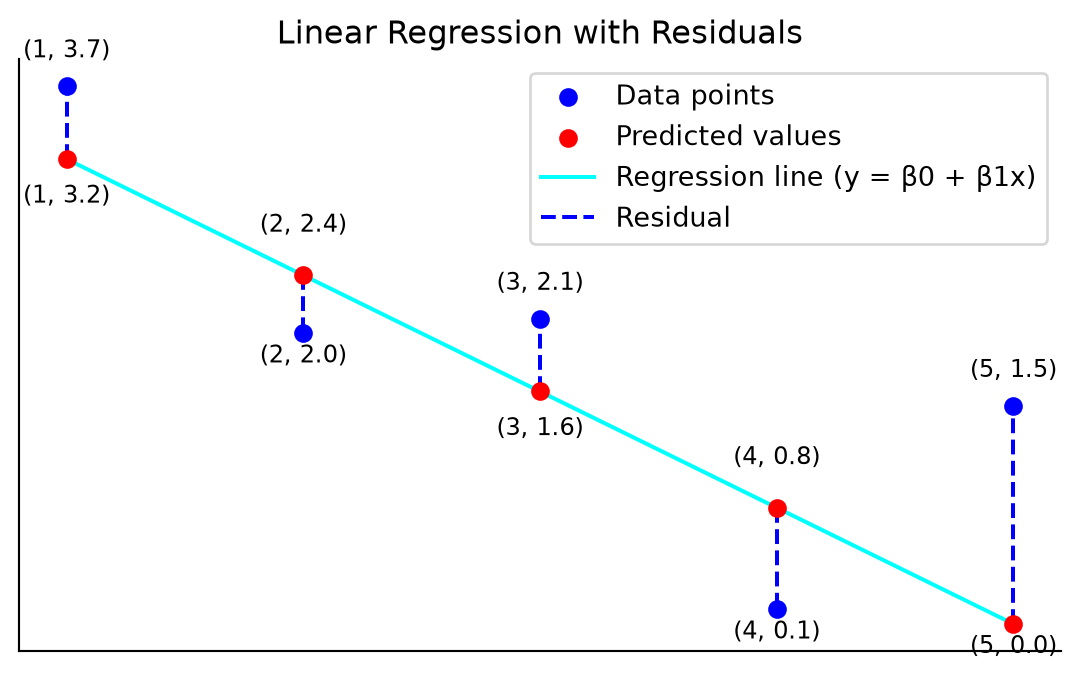
Suppose we have a line \(y = \beta_0 + \beta_1 x\).

For each data point \((x_j, y_j),\) there is a point \((x_j, \beta_0 + \beta_1 x_j)\) that is the point on the line with the same \(x\)-coordinate.

Code
def plot_residuals(x, y, beta_0, beta_1, figsize=(7, 4), title=None, legend=True):
    # scatter the data, draw the line y = beta_0 + beta_1 x, and mark each residual
    y_line = beta_0 + beta_1 * x

    fig, ax = plt.subplots(figsize=figsize)
    ax.scatter(x, y, color='blue', label='Data points', zorder=5)
    ax.scatter(x, y_line, color='red', label='Predicted values', zorder=5)
    ax.plot(x, y_line, color='cyan', label='Regression line (y = β0 + β1x)', zorder=4)

    # residuals: vertical segments from each point to the line
    for i in range(len(x)):
        ax.vlines(x[i], y_line[i], y[i], color='blue', linestyles='dashed',
                  label='Residual' if i == 0 else "", zorder=2)

    # label observed and predicted values, alternating above/below
    y_offset = [0.2, -0.2, 0.2, -0.2, 0.2]
    y_line_offset = [-0.3, 0.3, -0.3, 0.3, -0.2]
    for i in range(len(x)):
        ax.text(x[i], y[i] + y_offset[i], f'({x[i]}, {y[i]})', fontsize=9, ha='center')
        ax.text(x[i], y_line[i] + y_line_offset[i], f'({x[i]}, {y_line[i]:.1f})', fontsize=9, ha='center')

    ax.spines['top'].set_color('none')
    ax.spines['right'].set_color('none')
    ax.xaxis.set_ticks([])
    ax.yaxis.set_ticks([])
    if title:
        ax.set_title(title)
    if legend:
        ax.legend()
    return ax

x = np.array([1, 2, 3, 4, 5])
y = np.array([3.7, 2.0, 2.1, 0.1, 1.5])
plot_residuals(x, y, beta_0=4, beta_1=-0.8, title='Linear Regression with Residuals')
plt.show()

Least-Squares Lines cont.

We call

  • \(y_j\) the observed value of \(y\) and
  • \(\beta_0 + \beta_1 x_j\) the predicted \(y\)-value.

The difference between an observed \(y\)-value and a predicted \(y\)-value is called a residual.

There are several ways to measure how “close” the line is to the data.

The usual choice is to sum the squares of the residuals.

The least-squares line is the line \(y = \beta_0 + \beta_1x\) that minimizes the sum of squares of the residuals.

The coefficients \(\beta_0, \beta_1\) of the line are called regression coefficients.

A least-squares problem

If the data points were on the line, the parameters \(\beta_0\) and \(\beta_1\) would satisfy the equations

\[ \begin{align*} \beta_0 + \beta_1 x_1 &= y_1, \\ \beta_0 + \beta_1 x_2 &= y_2, \\ \beta_0 + \beta_1 x_3 &= y_3, \\ &\vdots \\ \beta_0 + \beta_1 x_n &= y_n. \end{align*} \]

We can write this system as

\[ X\boldsymbol\beta = \mathbf{y}, \]

where

\[ X= \begin{bmatrix} 1 & x_1 \\ 1 & x_2 \\ \vdots & \vdots \\ 1 & x_n \end{bmatrix}, \;\;\boldsymbol\beta = \begin{bmatrix}\beta_0\\\beta_1\end{bmatrix}, \;\;\mathbf{y}=\begin{bmatrix}y_1\\y_2\\\vdots\\y_n\end{bmatrix}. \]

Of course, if the data points don’t actually lie exactly on a line,

… then there are no parameters \(\beta_0, \beta_1\) for which the predicted \(y\)-values in \(X\boldsymbol\beta\) equal the observed \(y\)-values in \(\mathbf{y}\),

… and \(X\boldsymbol\beta=\mathbf{y}\) has no solution.

Now, since the data doesn’t fall exactly on a line, we have decided to seek the \(\boldsymbol\beta\) that minimizes the sum of squared residuals, i.e.,

\[ \sum_i (\beta_0 + \beta_1 x_i - y_i)^2 =\Vert X\boldsymbol\beta -\mathbf{y}\Vert^2. \]

This is key:

Important

The sum of squares of the residuals is exactly the square of the distance between the vectors \(X\boldsymbol\beta\) and \(\mathbf{y}.\)

Computing the least-squares solution of \(X\boldsymbol\beta = \mathbf{y}\) is equivalent to finding the \(\boldsymbol\beta\) that determines the least-squares line.

Code
ax = plt.figure(figsize = (5, 5)).add_subplot()
centerAxes(ax)
line = np.array([1, 0.5])
np.random.seed(1)
xlin = -10.0 + 20.0 * np.random.random(100)
ylin = line[0] + (line[1] * xlin) + np.random.randn(100)
ax.plot(xlin, ylin, 'ro', markersize = 4)
ax.plot(xlin, line[0] + line[1] * xlin, 'b-')
plt.text(-9, 3, r'$y = \beta_0 + \beta_1x$', size=20)
plt.show()

Now, to obtain the least-squares line, find the least-squares solution to \(X\boldsymbol\beta = \mathbf{y}.\)

Where does that solution come from? Not from a formula to memorize – from a picture.

Least squares is a projection

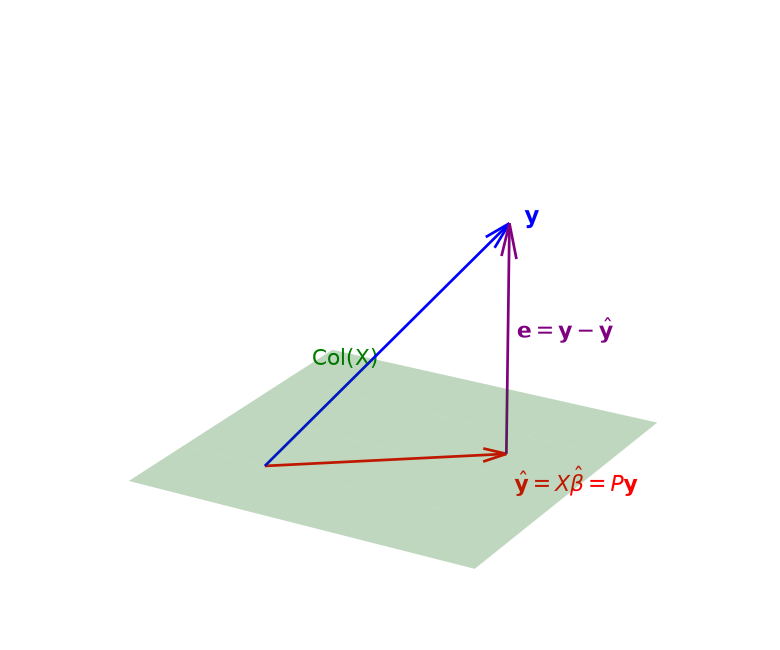
  • As \(\boldsymbol\beta\) varies, \(X\boldsymbol\beta\) ranges over the column space \(\text{Col}(X)\): all linear combinations of the columns of \(X\).
  • We want the point \(\hat{\mathbf{y}} = X\hat{\boldsymbol\beta}\) of \(\text{Col}(X)\) that is closest to \(\mathbf{y}\).
  • The closest point of a subspace is the orthogonal projection of \(\mathbf{y}\) onto it. So the residual \(\mathbf{e} = \mathbf{y} - \hat{\mathbf{y}}\) is perpendicular to the subspace, hence to every column of \(X\): \[X^T(\mathbf{y} - X\hat{\boldsymbol\beta}) = \mathbf{0}.\]

The same condition from calculus

The loss is the squared length of the residual, \(\lVert \mathbf{y} - X\boldsymbol\beta \rVert^2\). Its gradient is

\[ \nabla_{\boldsymbol\beta} \lVert \mathbf{y} - X\boldsymbol\beta \rVert^2 = -2\,X^T(\mathbf{y} - X\boldsymbol\beta), \]

and setting it to zero gives the previous slide’s condition:

\[ X^T(\mathbf{y} - X\hat{\boldsymbol\beta}) = \mathbf{0}. \]

The geometry says why it holds; the derivative gives an equation to solve. It is a minimum, not just a flat point, because the loss is a convex bowl.

The normal equations

Rearranging \(X^T(\mathbf{y} - X\hat{\boldsymbol\beta}) = \mathbf{0}\) gives the normal equations:

\[ X^TX\hat{\boldsymbol\beta} = X^T\mathbf{y}. \]

They say exactly this: the residual \(X\hat{\boldsymbol\beta} - \mathbf{y}\) is normal (i.e. orthogonal) to the column space of \(X\).

The normal equations always have at least one solution (\(X^T\mathbf{y}\) lies in the column space of \(X^T\), which equals the column space of \(X^TX\)).

If \(X^TX\) is invertible, the solution is unique:

\[ \hat{\boldsymbol\beta} = (X^TX)^{-1} X^T\mathbf{y}. \]

The normal equations by hand

The five points from the residual plot, fit with \(y = \beta_0 + \beta_1 x\):

\[ X = \begin{bmatrix} 1 & 1 \\ 1 & 2 \\ 1 & 3 \\ 1 & 4 \\ 1 & 5 \end{bmatrix}, \qquad \mathbf{y} = \begin{bmatrix} 3.7 \\ 2.0 \\ 2.1 \\ 0.1 \\ 1.5 \end{bmatrix} \]

\[ X^TX = \begin{bmatrix} 5 & 15 \\ 15 & 55 \end{bmatrix}, \qquad X^T\mathbf{y} = \begin{bmatrix} 9.4 \\ 21.9 \end{bmatrix} \]

\[ \begin{aligned} 5\beta_0 + 15\beta_1 &= 9.4 \\ 15\beta_0 + 55\beta_1 &= 21.9 \end{aligned} \]

Triple the first and subtract:

\[ 10\beta_1 = -6.3 \;\Rightarrow\; \hat\beta_1 = -0.63, \quad \hat\beta_0 = 3.77 \]

Residual sum of squares: \(2.72\), below the \(3.4\) of the line we drew earlier.

The hat matrix

Substitute \(\hat{\boldsymbol\beta}\) back into \(\hat{\mathbf{y}} = X\hat{\boldsymbol\beta}\):

\[ \hat{\mathbf{y}} = X(X^TX)^{-1}X^T\mathbf{y} = P\mathbf{y}. \]

\(P = X(X^TX)^{-1}X^T\) is the projection matrix, or hat matrix (it puts the hat on \(\mathbf{y}\)). It depends only on \(X\), not on \(\mathbf{y}\).

  • \(P\) is symmetric (\(P^T = P\)) and idempotent (\(P^2 = P\)): projecting twice changes nothing.
  • \(\operatorname{tr} P = p\), the number of columns of \(X\): the fit “uses up” \(p\) degrees of freedom.
  • The residual is \(\mathbf{e} = (I - P)\mathbf{y}\), and \(\hat{\mathbf{y}}^T\mathbf{e} = \mathbf{y}^TP(I-P)\mathbf{y} = 0\): fitted values and residuals are orthogonal. That is Pythagoras, \(\|\mathbf{y}\|^2 = \|\hat{\mathbf{y}}\|^2 + \|\mathbf{e}\|^2\), and it becomes \(\text{TSS} = \text{RSS} + \text{ESS}\) below.
  • The diagonal entry \(P_{ii}\) is the leverage of observation \(i\): how hard \(y_i\) pulls on its own fitted value. It returns when we look at residuals.

When is \(X^TX\) invertible?

For \(X\) an \(n \times p\) matrix (\(n\) observations, \(p\) columns):

\[ X^TX \text{ is invertible} \iff X \text{ has full column rank, i.e. } \operatorname{rank}(X) = p, \]

meaning no column of \(X\) is a linear combination of the others.

This requires \(n \geq p\) (at least as many observations as columns), but \(n \ge p\) alone is not enough: two identical columns make \(X^TX\) singular at any \(n\).

When \(X^TX\) is singular the normal equations still have solutions – infinitely many. The fitted values \(\hat{\mathbf{y}} = P\mathbf{y}\) are still unique (the projection is), but the coefficients are not: the fit is determined, \(\boldsymbol\beta\) is not. Nearly collinear columns cause the same trouble in a milder form, which is where regularization comes in next lecture.

The General Linear Model

The General Linear Model

Another way that the inconsistent (i.e. no exact solution) linear system is often written is to collect all the residuals into a residual vector.

Then an exact equation is

\[ \mathbf{y} = X\boldsymbol\beta + \boldsymbol\epsilon, \]

where \(\boldsymbol\epsilon\) is the residual vector.

Any equation of this form is referred to as a linear model.

In this formulation, the goal is to find the \(\boldsymbol\beta\) so as to minimize the norm of \(\boldsymbol\epsilon\), i.e., \(\Vert\boldsymbol\epsilon\Vert.\)

In some cases, one would like to fit data points with something other than a straight line.

In cases like this, the matrix equation is still \(X\boldsymbol\beta = \mathbf{y}\), but the specific form of \(X\) changes from one problem to the next.

Least-Squares Fitting of Other Models

In model fitting, the parameters of the model are what is unknown.

A central question for us is whether the model is linear in its parameters.

For example, is this model linear in its parameters?

\[ y = \beta_0 e^{-\beta_1 x} \]

It is not linear in its parameters.

Is this model linear in its parameters?

\[ y = \beta_0 e^{-2 x} \]

It is linear in its parameters.

For a model that is linear in its parameters, an observation is a linear combination of (arbitrary) known functions.

In other words, a model that is linear in its parameters is

\[ y = \beta_0f_0(x) + \beta_1f_1(x) + \dots + \beta_{p-1}f_{p-1}(x) \]

where \(f_0, \dots, f_{p-1}\) are \(p\) known functions (they become the \(p\) columns of \(X\)) and \(\beta_0,\dots,\beta_{p-1}\) are parameters.

Example

Suppose data points \((x_1, y_1), \dots, (x_n, y_n)\) appear to lie along some sort of parabola instead of a straight line.

Code
ax = plt.figure(figsize = (5, 5)).add_subplot()
centerAxes(ax)
quad = np.array([1, 3, 0.5])
np.random.seed(1)
xquad = -10.0 + 20.0 * np.random.random(100)
yquad = quad[0] + (quad[1] * xquad) + (quad[2] * xquad * xquad) + 2*np.random.randn(100)
ax.plot(xquad, yquad, 'ro', markersize = 4)
plt.show()

As a result, we wish to approximate the data by an equation of the form

\[ y = \beta_0 + \beta_1x + \beta_2x^2. \]

Let’s describe the linear model that produces a “least squares fit” of the data by the equation.

Solution

The ideal relationship is \(y = \beta_0 + \beta_1x + \beta_2x^2.\)

Suppose the actual values of the parameters are \(\beta_0, \beta_1, \beta_2.\)
Then the coordinates of the first data point satisfy the equation

\[ y_1 = \beta_0 + \beta_1x_1 + \beta_2x_1^2 + \epsilon_1, \]

where \(\epsilon_1\) is the residual error between the observed value \(y_1\) and the predicted \(y\)-value.

Each data point determines a similar equation:

\[ \begin{align*} y_1 &= \beta_0 + \beta_1x_1 + \beta_2x_1^2 + \epsilon_1, \\ y_2 &= \beta_0 + \beta_1x_2 + \beta_2x_2^2 + \epsilon_2, \\ &\vdots \\ y_n &= \beta_0 + \beta_1x_n + \beta_2x_n^2 + \epsilon_n. \end{align*} \]

Clearly, this system can be written as \(\mathbf{y} = X\boldsymbol\beta + \boldsymbol\epsilon.\)

\[ \begin{bmatrix} y_1\\ y_2\\ \vdots\\ y_n \end{bmatrix} = \begin{bmatrix}1&x_1&x_1^2\\ 1&x_2&x_2^2\\ \vdots&\vdots&\vdots\\ 1&x_n&x_n^2 \end{bmatrix} \begin{bmatrix} \beta_0\\\ \beta_1\\\ \beta_2 \end{bmatrix} + \begin{bmatrix} \epsilon_1\\ \epsilon_2\\ \vdots\\ \epsilon_n \end{bmatrix} \]

Let’s solve for \(\boldsymbol\beta\), writing the formula out literally:

n = np.shape(xquad)[0]
X = np.array([np.ones(n), xquad, xquad**2]).T

# Solve for beta
beta = np.linalg.inv(X.T @ X) @ X.T @ yquad

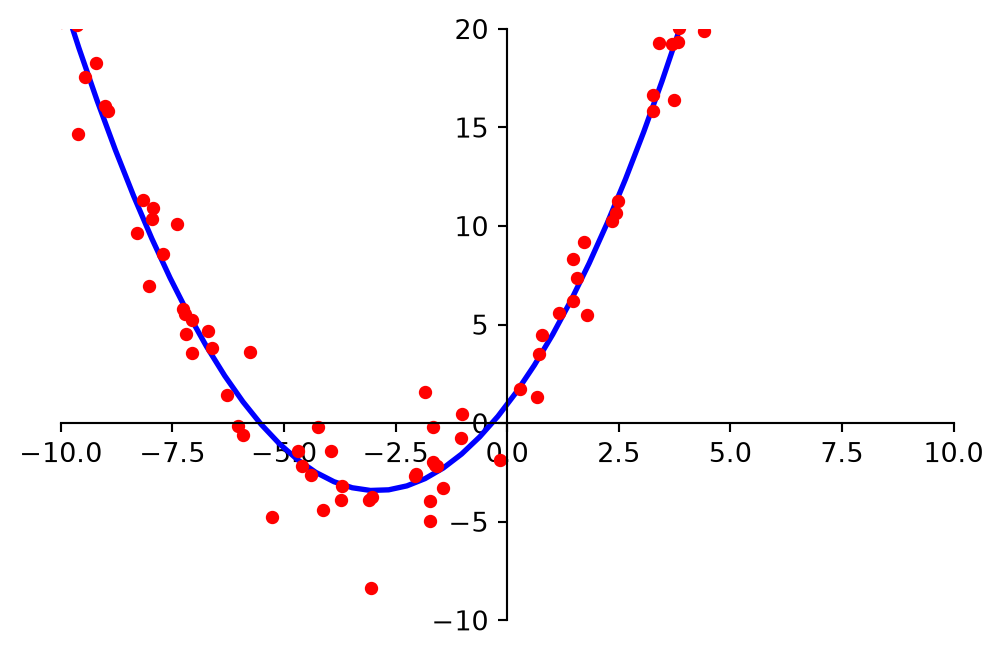
And plot the results.

Code
ax = ut.plotSetup(-10, 10, -10, 20)
ut.centerAxes(ax)
xplot = np.linspace(-10, 10, 50)
yestplot = beta[0] + beta[1] * xplot + beta[2] * xplot**2
ax.plot(xplot, yestplot, 'b-', lw=2)
ax.plot(xquad, yquad, 'ro', markersize=4)
plt.show()

Don’t actually invert \(X^TX\)

np.linalg.inv(X.T @ X) @ X.T @ y mirrors the formula and is fine for a first look, but forming the inverse is numerically unstable when columns of \(X\) are nearly collinear – small rounding errors in \(X^TX\) become large errors in \(\hat{\boldsymbol\beta}\). From here on we use np.linalg.lstsq(X, y), which solves the same least-squares problem stably (via a QR or SVD factorization); np.linalg.solve(X.T @ X, X.T @ y) is the other common choice.

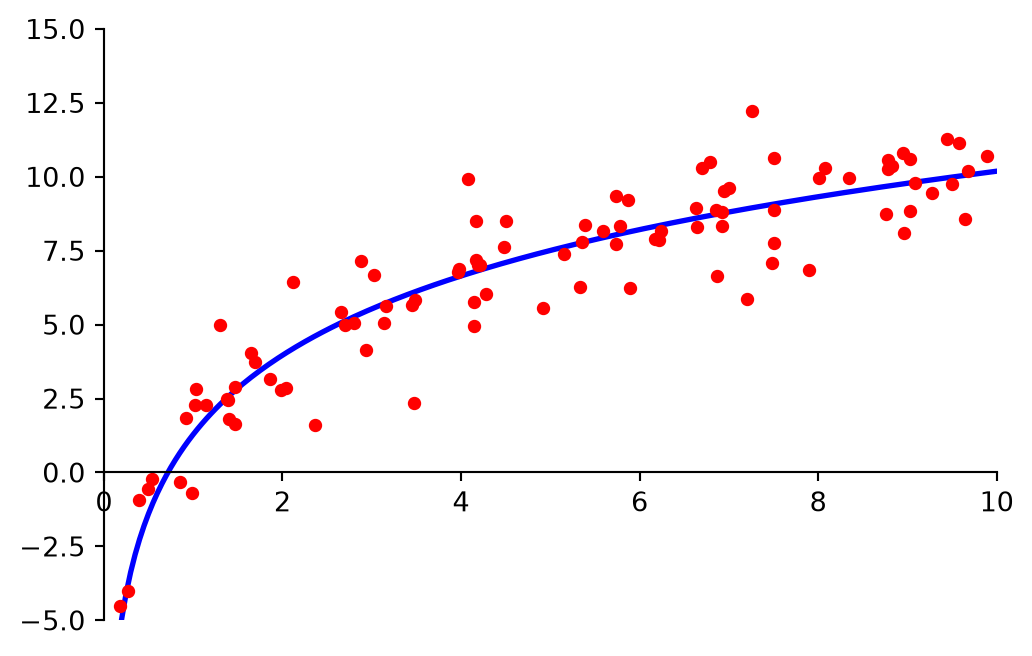
Now let’s try a different model.

\[ \begin{bmatrix} y_1\\ y_2\\ \vdots\\ y_n \end{bmatrix} = \begin{bmatrix}1&\log(x_1)\\ 1&\log(x_2)\\ \vdots&\vdots\\ 1&\log(x_n) \end{bmatrix} \begin{bmatrix} \beta_0\\\ \beta_1 \end{bmatrix} + \begin{bmatrix} \epsilon_1\\ \epsilon_2\\ \vdots\\ \epsilon_n \end{bmatrix} \]

n = np.shape(xlog)[0]
X = np.array([np.ones(n), np.log(xlog)]).T

# Solve for beta, stably this time
beta, *_ = np.linalg.lstsq(X, ylog, rcond=None)

And plot the results.

Code
# 
# plot the results
#
ax = ut.plotSetup(0, 10, -5, 15)
ut.centerAxes(ax)
xplot = np.linspace(0.05, 10, 200)
yestplot = beta[0] + beta[1] * np.log(xplot)
ax.plot(xplot,yestplot,'b-',lw=2)
ax.plot(xlog,ylog,'ro',markersize=4)
plt.show()

Multiple Regression

Suppose an experiment involves two independent variables – say, \(u\) and \(v\), – and one dependent variable, \(y\).

A simple equation for predicting \(y\) from \(u\) and \(v\) has the form

\[ y = \beta_0 + \beta_1 u + \beta_2 v. \]

Since there is more than one independent variable, this is called multiple regression.

Multiple Regression, cont.

A more general prediction equation might have the form

\[ y = \beta_0 + \beta_1 u + \beta_2 v + \beta_3u^2 + \beta_4 uv + \beta_5 v^2. \]

A least squares fit to equations like this is called a trend surface.

In general, a linear model will arise whenever \(y\) is to be predicted by an equation of the form

\[ y = \beta_0f_0(u,v) + \beta_1f_1(u,v) + \cdots + \beta_{p-1}f_{p-1}(u,v), \]

with \(f_0,\dots,f_{p-1}\) any sort of known functions and \(\beta_0,\dots,\beta_{p-1}\) unknown weights.

Example

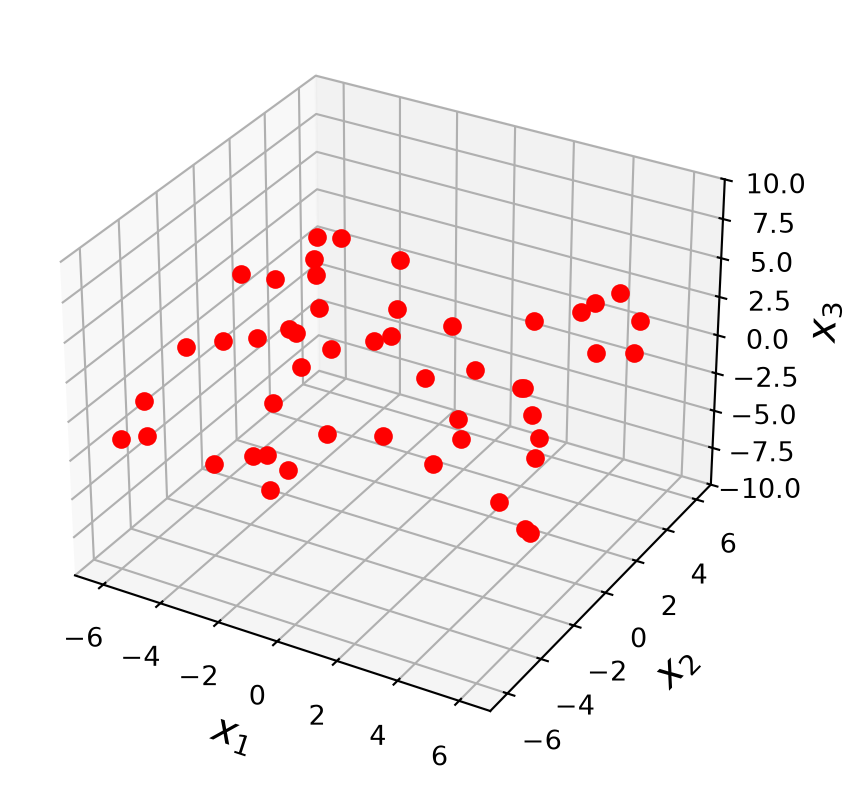
Let’s take an example. Here are a set of points in \(\mathbb{R}^3\):

Code
ax = ut.plotSetup3d(-7, 7, -7, 7, -10, 10, figsize = (5, 5))
v = [4.0, 4.0, 2.0]
u = [-4.0, 3.0, 1.0]
npts = 50

# set locations of points that fall within x,y
np.random.seed(1)
xc = -7.0 + 14.0 * np.random.random(npts)
yc = -7.0 + 14.0 * np.random.random(npts)
A = np.array([u,v]).T

# project these points onto the plane
P = A @ np.linalg.inv(A.T @ A) @ A.T
coords = P @ np.array([xc, yc, np.zeros(npts)])
coords[2] += np.random.randn(npts)
ax.plot(coords[0], coords[1], 'ro', zs=coords[2], markersize = 6)
plt.show()

Example

In geography, local models of terrain are constructed from data

\[ (u_1, v_1, z_1), \dots, (u_n, v_n, z_n), \]

where \(u_j, v_j\), and \(z_j\) are latitude, longitude, and altitude, respectively.

Let’s describe the linear models that gives a least-squares fit to such data.
The solution is called the least-squares plane.

Solution

The model is \(z = \beta_0 + \beta_1 u + \beta_2 v + \epsilon\): altitude as a linear function of latitude and longitude. We expect the data to satisfy these equations:

\[ \begin{align*} z_1 &= \beta_0 + \beta_1 u_1 + \beta_2 v_1 + \epsilon_1, \\ z_2 &= \beta_0 + \beta_1 u_2 + \beta_2 v_2 + \epsilon_2, \\ \vdots \\ z_n &= \beta_0 + \beta_1 u_n + \beta_2 v_n + \epsilon_n. \end{align*} \]

This system has the matrix form \(\mathbf{z} = X\boldsymbol\beta + \boldsymbol\epsilon,\) with an \(n \times 3\) design matrix \(X\):

\[ \mathbf{z} = \begin{bmatrix}z_1\\ z_2\\ \vdots\\ z_n \end{bmatrix},\;\; X = \begin{bmatrix}1&u_1&v_1\\ 1&u_2&v_2\\ \vdots&\vdots&\vdots\\ 1&u_n&v_n \end{bmatrix},\;\; \boldsymbol\beta= \begin{bmatrix} \beta_0\\ \beta_1\\ \beta_2 \end{bmatrix},\;\; \boldsymbol\epsilon = \begin{bmatrix} \epsilon_1\\ \epsilon_2\\ \vdots\\ \epsilon_n \end{bmatrix}. \]

Code
u_obs, v_obs, z_obs = coords

# design matrix [1, u, v] and the least-squares plane
X_plane = np.column_stack([np.ones(npts), u_obs, v_obs])
beta_plane, *_ = np.linalg.lstsq(X_plane, z_obs, rcond=None)
z_hat = X_plane @ beta_plane

ax = ut.plotSetup3d(-7, 7, -7, 7, -10, 10, figsize = (7, 7))
ax.set_xlabel('$u$', size=15)
ax.set_ylabel('$v$', size=15)
ax.set_zlabel('$z$', size=15)

# the fitted plane ...
uu, vv = np.meshgrid(np.linspace(-7, 7, 10), np.linspace(-7, 7, 10))
ax.plot_surface(uu, vv, beta_plane[0] + beta_plane[1] * uu + beta_plane[2] * vv,
                color='green', alpha=0.3)
# ... and the residual from each point to it
for ui, vi, zi, zh in zip(u_obs, v_obs, z_obs, z_hat):
    ax.plot([ui, ui], [vi, vi], [zi, zh], 'b-', lw=1)
ax.plot(u_obs, v_obs, 'ro', zs=z_obs, markersize=6)
plt.show()

The green surface is the fitted plane \(\hat z = \hat\beta_0 + \hat\beta_1 u + \hat\beta_2 v\); the blue segments are the residuals it minimizes (in the sum of squares).

This example shows that the linear model for multiple regression has the same form as the model for the simple regression in the earlier examples.

We can see that the general principle is the same across all the different kinds of linear models.

Once \(X\) is defined properly, the normal equations for \(\boldsymbol\beta\) have the same matrix form, no matter how many variables are involved.

Thus, for any linear model where \(X^TX\) is invertible, the least squares estimate is

\[ \hat{\boldsymbol\beta} = (X^TX)^{-1}X^T\mathbf{y}. \]

Measuring the fit of a regression model

Measuring the fit of a regression model: \(R^2\)

Given any \(X\) and \(\mathbf{y}\), the above algorithm will produce an output \(\hat{\boldsymbol\beta}\).

But how do we know whether the data is in fact well described by the model?

The most common measure of fit is \(R^2\).

\(R^2\) measures the fraction of the variance of \(\mathbf{y}\) that can be explained by the model \(X\hat{\boldsymbol\beta}\).

The variance of \(\mathbf{y}\) is

\[ \text{Var}(\mathbf{y}) =\frac{1}{n} \sum_{i=1}^n \left(y_i-\overline{y}\right)^2, \]

where \(\overline{y}=\frac{1}{n}\sum_{i=1}^ny_i\).

Measuring the fit, cont.

For any given \(n\), we can equally work with just \[ \sum_{i=1}^n \left(y_i-\overline{y}\right)^2, \]

which is called the Total Sum of Squares (TSS).

Total Sum of Squares

Now to measure the quality of fit of a model, we break TSS down into two components.

For any given \(\mathbf{x}_i\), the prediction made by the model is \(\hat{y_i} = \mathbf{x}_i^T\boldsymbol\beta\).

We can break the total sum of squares into two parts by adding and subtracting the predicted value \(\hat{y_i}\) for each \(i\):

\[ \sum_{i=1}^n \left[(y_i-\hat{y_i}) + (\hat{y_i}-\overline{y})\right]^2, \]

  • we call \(\epsilon_i\) is \(y_i - \hat{y_i}\) the residual, and
  • the part that the model “explains” is \(\hat{y_i} - \overline{y}.\)

RSS and ESS

So we define the Residual Sum of Squares (RSS) as:

\[ \text{RSS} = \sum_{i=1}^n \left(y_i-\hat{y_i}\right)^2, \]

and the Explained Sum of Squares (ESS) as:

\[ \text{ESS} = \sum_{i=1}^n \left(\hat{y_i}-\overline{y}\right)^2, \]

One can show1 that the total sum of squares is exactly equal to the sum of squares of the residuals plus the sum of squares of the explained part.

In other words:

\[ \text{TSS} = \text{RSS} + \text{ESS}. \]

\(R^2\), cont.

Now, a good fit is one in which the model explains a large part of the variance of \(\mathbf{y}\).

So the measure of fit \(R^2\) is defined as:

\[ R^2 = \frac{\text{ESS}}{\text{TSS}} = 1-\frac{\text{RSS}}{\text{TSS}} = 1 - \frac{\sum_{i=1}^n \left(y_i-\hat{y_i}\right)^2}{\sum_{i=1}^n \left(y_i-\overline{y}\right)^2}. \]

As a result, \(0\leq R^2\leq 1\) – on the training data, for a model with an intercept. That is what makes \(\text{TSS} = \text{RSS} + \text{ESS}\) hold.

Computed on held-out data (e.g. validation or test) (as r2_score does for Ames below) RSS can exceed TSS, and \(R^2\) can be negative: the model predicts worse than the constant \(\overline{y}\).

This is more specifically called the centered \(R^2\); it assumes an intercept. We will meet the uncentered variant in a moment, when a software package quietly switches to it.

\(R^2\), cont.

The closer the value of \(R^2\) is to \(1\) the better the fit of the regression:

  • small values of RSS imply that the residuals are small and therefore we have a better fit.

\(R^2\) is called the coefficient of determination.

It tells us “how well does the model predict the data?”

\(R^2\) and Pearson’s \(r\)

\(R^2\) is related to, but not the same thing as, Pearson’s correlation coefficient \(r\).

  • For simple regression (one feature plus an intercept), \(R^2 = r^2\) exactly, where \(r = \text{corr}(x, y)\). That is where the notation comes from, and why people sometimes write \(r^2\).
  • In general (any number of features, with an intercept, in-sample), \[R^2 = \text{corr}(\mathbf{y}, \hat{\mathbf{y}})^2,\] the squared correlation between the observations and the model’s predictions.
  • So \(R^2\) is a correlation squared, but between \(\mathbf{y}\) and \(\hat{\mathbf{y}}\), not between two raw variables. Two features can each be correlated with \(y\) while the model built from them predicts it poorly; to judge predictions against ground truth, use \(R^2\) (and use it on held-out data).

OLS in Practice

OLS in Practice

First, we’ll look at a test case on synthetic data. We’ll use Scikit-Learn’s make_regression function.

from sklearn import datasets
X, y = datasets.make_regression(n_samples=100, n_features=20, n_informative=5, bias=0.1, noise=30, random_state=1)

And then use the statsmodels package to fit the model.

import statsmodels.api as sm

# statsmodels does not add an intercept for you: prepend a column of ones
X_with_intercept = sm.add_constant(X)

model = sm.OLS(y, X_with_intercept)
results = model.fit()

And print the summary of the results.

Code
print(results.summary())
                            OLS Regression Results                            
==============================================================================
Dep. Variable:                      y   R-squared:                       0.969
Model:                            OLS   Adj. R-squared:                  0.961
Method:                 Least Squares   F-statistic:                     124.5
Date:                Fri, 16 Oct 2026   Prob (F-statistic):           2.66e-51
Time:                        15:17:14   Log-Likelihood:                -467.24
No. Observations:                 100   AIC:                             976.5
Df Residuals:                      79   BIC:                             1031.
Df Model:                          20                                         
Covariance Type:            nonrobust                                         
==============================================================================
                 coef    std err          t      P>|t|      [0.025      0.975]
------------------------------------------------------------------------------
const         -4.2494      3.268     -1.300      0.197     -10.754       2.255
x1            11.5637      3.542      3.265      0.002       4.514      18.613
x2            -3.3068      2.835     -1.166      0.247      -8.950       2.336
x3            -1.8897      3.475     -0.544      0.588      -8.806       5.026
x4             2.4164      3.088      0.783      0.436      -3.730       8.563
x5            -2.2111      3.445     -0.642      0.523      -9.068       4.645
x6             1.0613      3.152      0.337      0.737      -5.213       7.336
x7            -2.9127      3.582     -0.813      0.419     -10.043       4.217
x8            90.5856      3.216     28.166      0.000      84.184      96.987
x9            -0.2241      3.389     -0.066      0.947      -6.970       6.522
x10           15.4059      3.236      4.761      0.000       8.965      21.847
x11            0.6029      3.385      0.178      0.859      -6.134       7.340
x12            0.8159      3.576      0.228      0.820      -6.302       7.933
x13           -0.2691      3.236     -0.083      0.934      -6.710       6.172
x14           90.6559      3.563     25.447      0.000      83.565      97.747
x15            1.0258      3.743      0.274      0.785      -6.425       8.477
x16            4.4945      2.731      1.646      0.104      -0.942       9.931
x17            9.9746      3.505      2.846      0.006       2.999      16.950
x18           72.9177      3.428     21.269      0.000      66.094      79.742
x19           -1.8957      3.500     -0.542      0.590      -8.861       5.070
x20           -0.8621      3.289     -0.262      0.794      -7.408       5.684
==============================================================================
Omnibus:                        5.973   Durbin-Watson:                   2.059
Prob(Omnibus):                  0.050   Jarque-Bera (JB):                5.386
Skew:                           0.483   Prob(JB):                       0.0677
Kurtosis:                       3.600   Cond. No.                         2.67
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.

The \(R^2\) value is very good. We can see that the linear model does a very good job of predicting the observations \(y_i\).

Uncentered \(R^2\)

sm.OLS does not add an intercept for you – hence sm.add_constant. Fit sm.OLS(y, X) on the raw X instead and the summary switches to the uncentered \(R^2\),

\[ R^2 (\text{uncentered}) = 1 - \frac{\sum_{i=1}^n \left(y_i-\hat{y_i}\right)^2}{\sum_{i=1}^n y_i^2}, \]

and says so in a footnote. Without a constant column the residuals need not sum to zero, \(\text{TSS} = \text{RSS} + \text{ESS}\) fails and the centered \(R^2\) can be negative, so statsmodels divides by \(\sum y_i^2\) instead of \(\sum (y_i - \overline{y})^2\). The uncentered number is almost always larger and is not comparable to the centered one. Try it.

What to read in the summary table

  • coef: \(\hat\beta_j\), the change in \(y\) per unit of \(x_j\) with the other columns held fixed.
  • std err: \(\text{SE}(\hat\beta_j) = \sqrt{\hat\sigma^2\,[(X^TX)^{-1}]_{jj}}\), the uncertainty in that estimate.
  • t and P>|t|: \(\hat\beta_j / \text{SE}\), and the probability of a \(t\) at least this large if the true coefficient were zero.
  • [0.025 0.975]: the 95% confidence interval \(\hat\beta_j \pm t_{0.025,\,n-p}\,\text{SE}(\hat\beta_j)\). If it contains zero, the data cannot tell \(\beta_j\) from zero.
  • R-squared and Adj. R-squared: fraction of variance explained; the adjusted version charges for each extra column, so it can go down.
  • F-statistic: tests “every non-intercept coefficient is zero”.
  • AIC, BIC: fit-minus-complexity scores for comparing models; lower is better.

The full glossary is in the web notes under Aside: Summary Statistics.

Back to the example.

Some of the independent variables may not contribute to the accuracy of the prediction.

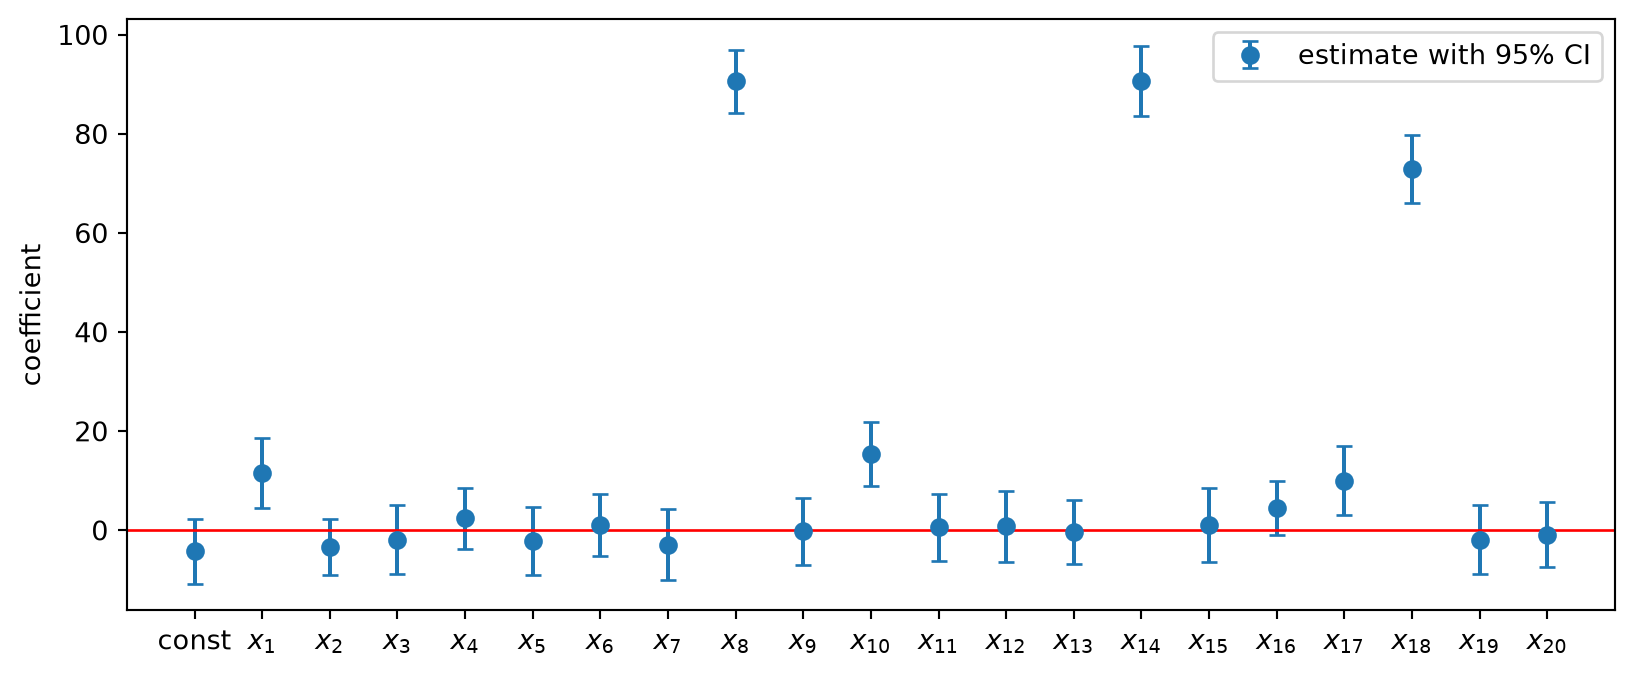
Each coefficient comes with a 95% confidence interval – the [0.025 0.975] columns of the table. Plotting them side by side makes the table readable at a glance:

Code
coef = results.params
CIs = results.conf_int()
names = ['const'] + [f'$x_{{{j}}}$' for j in range(1, X.shape[1] + 1)]  # match statsmodels' x1..x20

fig, ax = plt.subplots(figsize=(10, 4))
ax.errorbar(np.arange(len(coef)), coef,
            yerr=[coef - CIs[:, 0], CIs[:, 1] - coef],
            fmt='o', capsize=3, label='estimate with 95% CI')
ax.axhline(0, color='r', lw=1)
ax.set_xticks(np.arange(len(coef)))
ax.set_xticklabels(names)
ax.set_ylabel('coefficient')
ax.legend()
plt.show()

If a coefficient’s interval contains zero, the data cannot distinguish it from zero, and we cannot assume that there is any relationship between that independent variable and the observations. Six intervals sit clearly away from zero – but make_regression was told n_informative=5. One of the six is a false positive: at the 95% level, roughly one useless column in twenty will look significant by chance, and we have fifteen useless columns.

In other words, if the confidence interval for the parameter includes zero, the associated independent variable may not have any predictive value.

Code
print('Confidence Intervals: {}'.format(results.conf_int()))
print('Parameters: {}'.format(results.params))
Confidence Intervals: [[-10.75360184   2.25481398]
 [  4.51429102  18.61312008]
 [ -8.94962593   2.33603191]
 [ -8.80586069   5.02646873]
 [ -3.73021224   8.5631061 ]
 [ -9.06769657   4.64546658]
 [ -5.21308961   7.33575968]
 [-10.04254055   4.2172332 ]
 [ 84.18415371  96.98710861]
 [ -6.96971003   6.52150734]
 [  8.96511318  21.84671808]
 [ -6.13415773   7.33998878]
 [ -6.301506     7.93330272]
 [ -6.70975969   6.17158048]
 [ 83.56490018  97.74693301]
 [ -6.4252666    8.47684584]
 [ -0.94153416   9.93061264]
 [  2.9990259   16.95023827]
 [ 66.09389039  79.74158433]
 [ -8.8614541    5.07001186]
 [ -7.40787744   5.68373159]]
Parameters: [-4.24939393 11.56370555 -3.30679701 -1.88969598  2.41644693 -2.211115
  1.06133504 -2.91265367 90.58563116 -0.22410134 15.40591563  0.60291552
  0.81589836 -0.26908961 90.65591659  1.02578962  4.49453924  9.97463209
 72.91773736 -1.89572112 -0.86207292]

Find the independent variables that are not significant.

Code
CIs = results.conf_int()
notSignificant = (CIs[:,0] < 0) & (CIs[:,1] > 0)
notSignificant[0] = False   # always keep the intercept column
notSignificant
array([False, False,  True,  True,  True,  True,  True,  True, False,
        True, False,  True,  True,  True, False,  True,  True, False,
       False,  True,  True])

Let’s look at the shape of significant variables.

Code
Xsignif = X_with_intercept[:,~notSignificant]
Xsignif.shape
(100, 7)

A tempting next step is to drop the columns whose interval covers zero and refit:

Code
model = sm.OLS(y, Xsignif)
results = model.fit()
print(results.summary())
                            OLS Regression Results                            
==============================================================================
Dep. Variable:                      y   R-squared:                       0.966
Model:                            OLS   Adj. R-squared:                  0.964
Method:                 Least Squares   F-statistic:                     445.8
Date:                Fri, 16 Oct 2026   Prob (F-statistic):           3.21e-66
Time:                        15:17:14   Log-Likelihood:                -471.66
No. Observations:                 100   AIC:                             957.3
Df Residuals:                      93   BIC:                             975.5
Df Model:                           6                                         
Covariance Type:            nonrobust                                         
==============================================================================
                 coef    std err          t      P>|t|      [0.025      0.975]
------------------------------------------------------------------------------
const         -5.1888      2.927     -1.773      0.080     -11.001       0.623
x1            11.1097      3.161      3.515      0.001       4.833      17.386
x2            91.0034      2.685     33.890      0.000      85.671      96.336
x3            14.4371      2.891      4.993      0.000       8.696      20.179
x4            91.2173      3.273     27.868      0.000      84.717      97.717
x5             9.5400      3.072      3.105      0.003       3.439      15.641
x6            71.4542      3.080     23.201      0.000      65.338      77.570
==============================================================================
Omnibus:                       10.945   Durbin-Watson:                   2.133
Prob(Omnibus):                  0.004   Jarque-Bera (JB):               13.411
Skew:                           0.582   Prob(JB):                      0.00122
Kurtosis:                       4.366   Cond. No.                         1.67
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.

Pruning features, cont.

Here that is nearly harmless – make_regression built \(y\) from five informative columns, and we kept those five plus one impostor. In general, though, be careful: choosing the features and judging the fit on the same data is the Lecture 7 anti-pattern. The refit looks better than it is, because the selection step already used the noise in this sample (that is exactly how the impostor got in).

  • The honest version checks the smaller model on data it has not seen – which is exactly what we do for the Ames houses next.
  • Dropping a column is also an all-or-nothing choice. Next lecture’s regularization replaces manual pruning with a penalty that shrinks coefficients toward zero smoothly, and lets held-out data pick how hard to shrink.

Real Data: House Prices in Ames, Iowa

Let’s see how powerful multiple regression can be on a real-world example.

A typical application of linear models is predicting house prices.

Linear models have been used for this problem for decades, and when a municipality does a value assessment on your house, they typically use a linear model.

We can consider various measurable attributes of a house (its “features”) as the independent variables, and the most recent sale price of the house as the dependent variable.

For our case study, we will use the features:

  • Lot Area (sq ft),
  • Gross Living Area (sq ft),
  • Number of Fireplaces,
  • Number of Full Baths,
  • Number of Half Baths,
  • Garage Area (sq ft),
  • Basement Area (sq ft)

So our design matrix will have 8 columns (including the constant for the intercept):

\[ X\beta = \mathbf{y}, \]

and it will have one row for each house in the data set, with \(y\) the sale price of the house.

Ames Housing Data

We will use data from housing sales in Ames, Iowa from 2006 to 2009:

Ames Iowa

Tim Kiser (w:User:Malepheasant) CC BY-SA 2.5 via Wikimedia Commons

Code
import os, urllib.request

def data_file(path):
    """Course data file: use a local copy (here, or in the repo root above a
    notebook in jupyter_notebooks/), else fetch it from the Materials repo (Colab)."""
    for prefix in ('', '../'):
        if os.path.exists(prefix + path):
            return prefix + path
    os.makedirs(os.path.dirname(path) or '.', exist_ok=True)
    urllib.request.urlretrieve(
        'https://raw.githubusercontent.com/tools4ds/DS701-Materials-FA26/main/' + path, path)
    return path

df = pd.read_csv(data_file('data/ames-housing-data/train.csv'))
Code
df[['LotArea', 'GrLivArea', 'Fireplaces', 'FullBath', 'HalfBath', 'GarageArea', 'TotalBsmtSF', 'SalePrice']].head()
LotArea GrLivArea Fireplaces FullBath HalfBath GarageArea TotalBsmtSF SalePrice
0 8450 1710 0 2 1 548 856 208500
1 9600 1262 1 2 0 460 1262 181500
2 11250 1786 1 2 1 608 920 223500
3 9550 1717 1 1 0 642 756 140000
4 14260 2198 1 2 1 836 1145 250000

Some things to note here:

  • House prices are in dollars
  • Areas are in square feet
  • Rooms are in counts

Do we have scaling concerns here?

No, because each feature will get its own \(\beta\), which will correct for the scaling differences between different units of measure.

Code
X_no_intercept = df[['LotArea', 'GrLivArea', 'Fireplaces', 'FullBath', 'HalfBath', 'GarageArea', 'TotalBsmtSF']]
X_intercept = sm.add_constant(X_no_intercept)
y = df['SalePrice'].values

Note

Note that removing the intercept will cause the \(R^2\) to go up, which is counter-intuitive. The reason is explained here – but amounts to the fact that the formula for \(R^2\) with/without an intercept is different.

Ames Housing Data, cont.

Let’s split the data into training and test sets.

Code
from sklearn import utils, model_selection
X_train, X_test, y_train, y_test = model_selection.train_test_split(
    X_intercept, y, test_size = 0.5, random_state = 0)

Fit the model to the training data.

Code
model = sm.OLS(y_train, X_train)
results = model.fit()
print(results.summary())
                            OLS Regression Results                            
==============================================================================
Dep. Variable:                      y   R-squared:                       0.759
Model:                            OLS   Adj. R-squared:                  0.757
Method:                 Least Squares   F-statistic:                     325.5
Date:                Fri, 16 Oct 2026   Prob (F-statistic):          1.74e-218
Time:                        15:17:15   Log-Likelihood:                -8746.5
No. Observations:                 730   AIC:                         1.751e+04
Df Residuals:                     722   BIC:                         1.755e+04
Df Model:                           7                                         
Covariance Type:            nonrobust                                         
===============================================================================
                  coef    std err          t      P>|t|      [0.025      0.975]
-------------------------------------------------------------------------------
const       -4.285e+04   5350.784     -8.007      0.000   -5.34e+04   -3.23e+04
LotArea         0.2361      0.131      1.798      0.073      -0.022       0.494
GrLivArea      48.0865      4.459     10.783      0.000      39.332      56.841
Fireplaces   1.089e+04   2596.751      4.192      0.000    5787.515     1.6e+04
FullBath      1.49e+04   3528.456      4.224      0.000    7977.691    2.18e+04
HalfBath      1.56e+04   3421.558      4.559      0.000    8882.381    2.23e+04
GarageArea     98.9856      8.815     11.229      0.000      81.680     116.291
TotalBsmtSF    62.6392      4.318     14.508      0.000      54.163      71.116
==============================================================================
Omnibus:                      144.283   Durbin-Watson:                   1.937
Prob(Omnibus):                  0.000   Jarque-Bera (JB):              917.665
Skew:                           0.718   Prob(JB):                    5.39e-200
Kurtosis:                       8.302   Cond. No.                     6.08e+04
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
[2] The condition number is large, 6.08e+04. This might indicate that there are
strong multicollinearity or other numerical problems.

We see that we have:

  • \(\beta_0\): Intercept of -$42,850
  • \(\beta_1\): Marginal value of one square foot of Lot Area: $0.23
    • but NOTICE - this coefficient is not statistically different from zero!
  • \(\beta_2\): Marginal value of one square foot of Gross Living Area: $48
  • \(\beta_3\): Marginal value of one additional fireplace: $10,890
  • \(\beta_4\): Marginal value of one additional full bath: $14,900
  • \(\beta_5\): Marginal value of one additional half bath: $15,600
  • \(\beta_6\): Marginal value of one square foot of Garage Area: $99
  • \(\beta_7\): Marginal value of one square foot of Basement Area: $62

Coefficients are conditional slopes

Why is a half bath ($15,600) worth more than a full bath ($14,900)?

  • Each \(\beta_j\) holds the other six features fixed: \(\beta_5\) is the value of a half bath given the living area, basement, garage and so on.
  • Half baths co-occur with bigger, newer houses, and the coefficient absorbs some of what those features do not capture. Add or remove a correlated feature and the other coefficients move.
  • A coefficient is a conditional slope, not a price tag – and not a causal claim. Adding a half bath to your house will not raise its price by $15,600.

Is our model doing a good job?

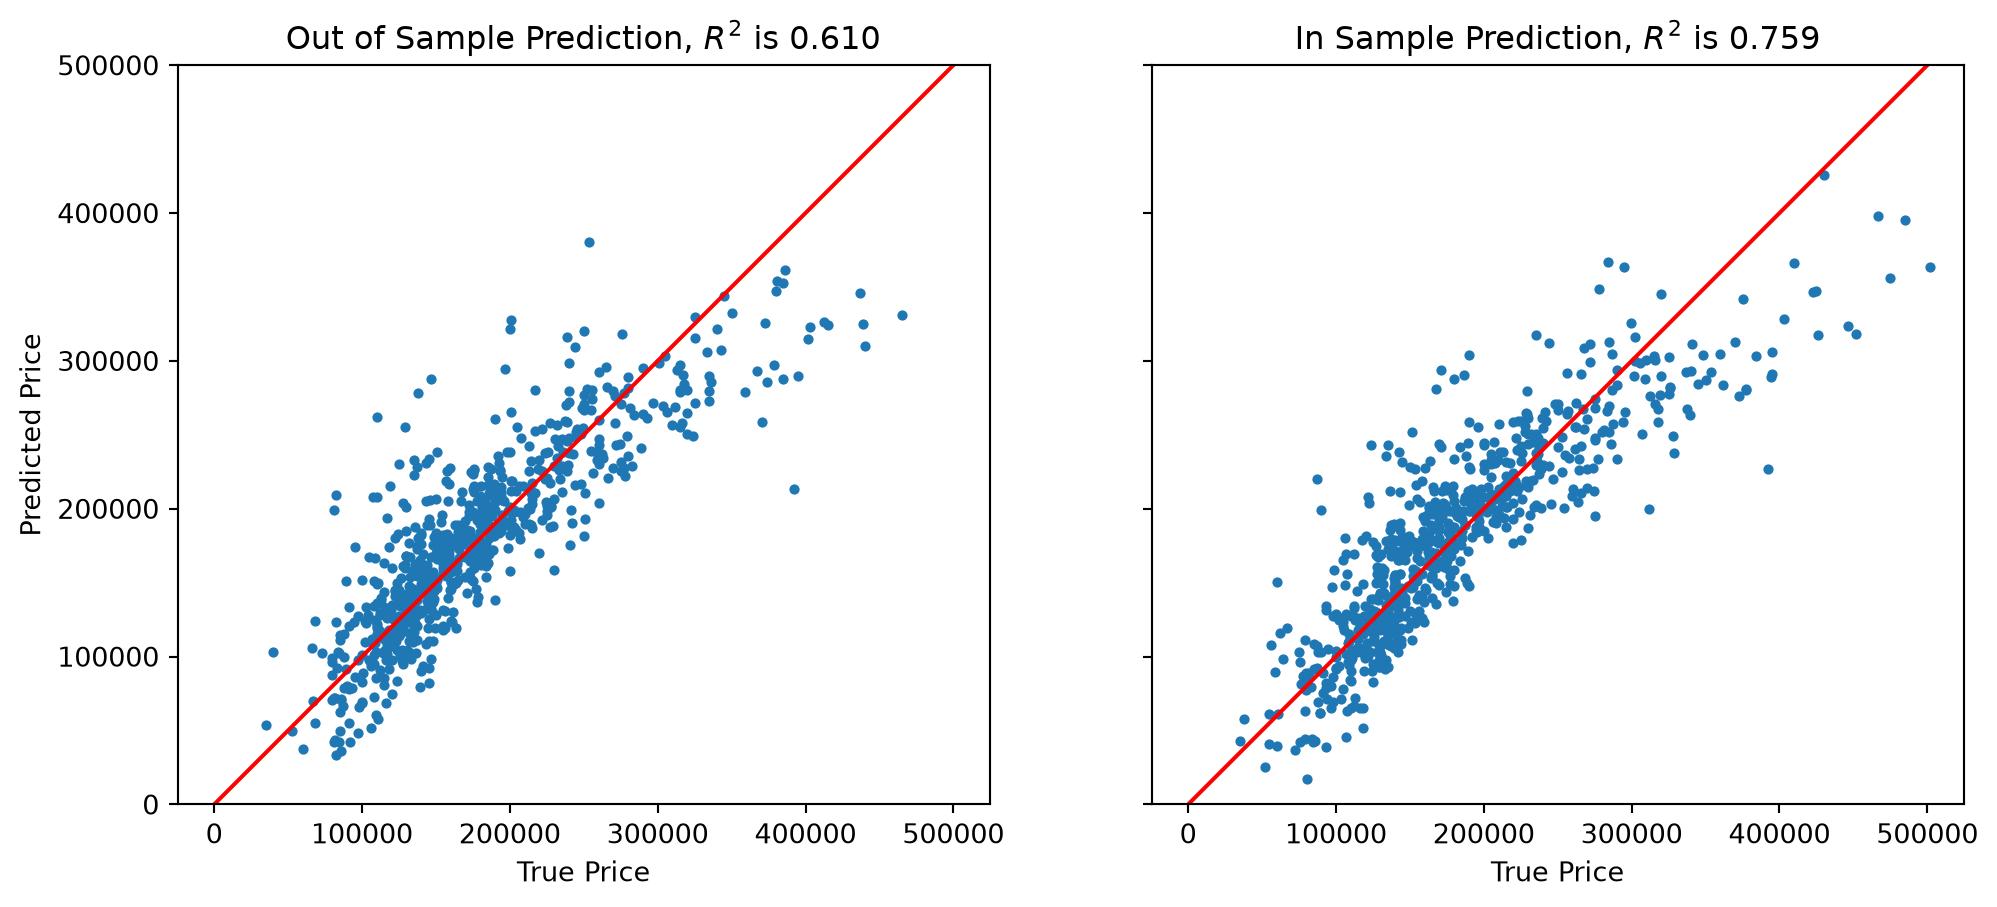
The summary table offers many statistics, but two pictures tell us more: the predictions against the ground truth, and then the residuals against the fitted values.

For each house we compute its predicted sale value according to our model:

\[ \hat{\mathbf{y}} = X\hat{\boldsymbol\beta} \]

Code
from sklearn.metrics import r2_score

fig, (ax1, ax2) = plt.subplots(1,2,sharey = 'row', figsize=(12, 5))
y_oos_predict = results.predict(X_test)
r2_test = r2_score(y_test, y_oos_predict)
ax1.scatter(y_test, y_oos_predict, s = 8)
ax1.set_xlabel('True Price')
ax1.set_ylabel('Predicted Price')
ax1.plot([0,500000], [0,500000], 'r-')
ax1.axis('equal')
ax1.set_ylim([0, 500000])
ax1.set_xlim([0, 500000])
ax1.set_title(f'Out of Sample Prediction, $R^2$ is {r2_test:0.3f}')
#
y_is_predict = results.predict(X_train)
ax2.scatter(y_train, y_is_predict, s = 8)
r2_train = r2_score(y_train, y_is_predict)
ax2.set_xlabel('True Price')
ax2.plot([0,500000],[0,500000],'r-')
ax2.axis('equal')
ax2.set_ylim([0,500000])
ax2.set_xlim([0,500000])
ax2.set_title(f'In Sample Prediction, $R^2$ is {r2_train:0.3f}')
plt.show()
Ignoring fixed x limits to fulfill fixed data aspect with adjustable data limits.

We see that the model does a reasonable job in the middle of the price range, where most of the houses are.

At both ends the predictions are pulled toward the mean: cheap houses are over-predicted and expensive ones under-predicted. That is not a bug in this particular fit. \(\hat{\mathbf{y}}\) is a projection of \(\mathbf{y}\), so it is the shorter vector and \(\text{Var}(\hat{\mathbf{y}}) \le \text{Var}(\mathbf{y})\): fitted values are always less spread out than the truth. This is Galton’s regression to the mean, now falling out of the algebra.

Note that the \(R^2\) on the (held out) test data is 0.610, against 0.759 in sample. We are not doing as well on test data as on training data (somewhat to be expected).

Ames: look at the residuals

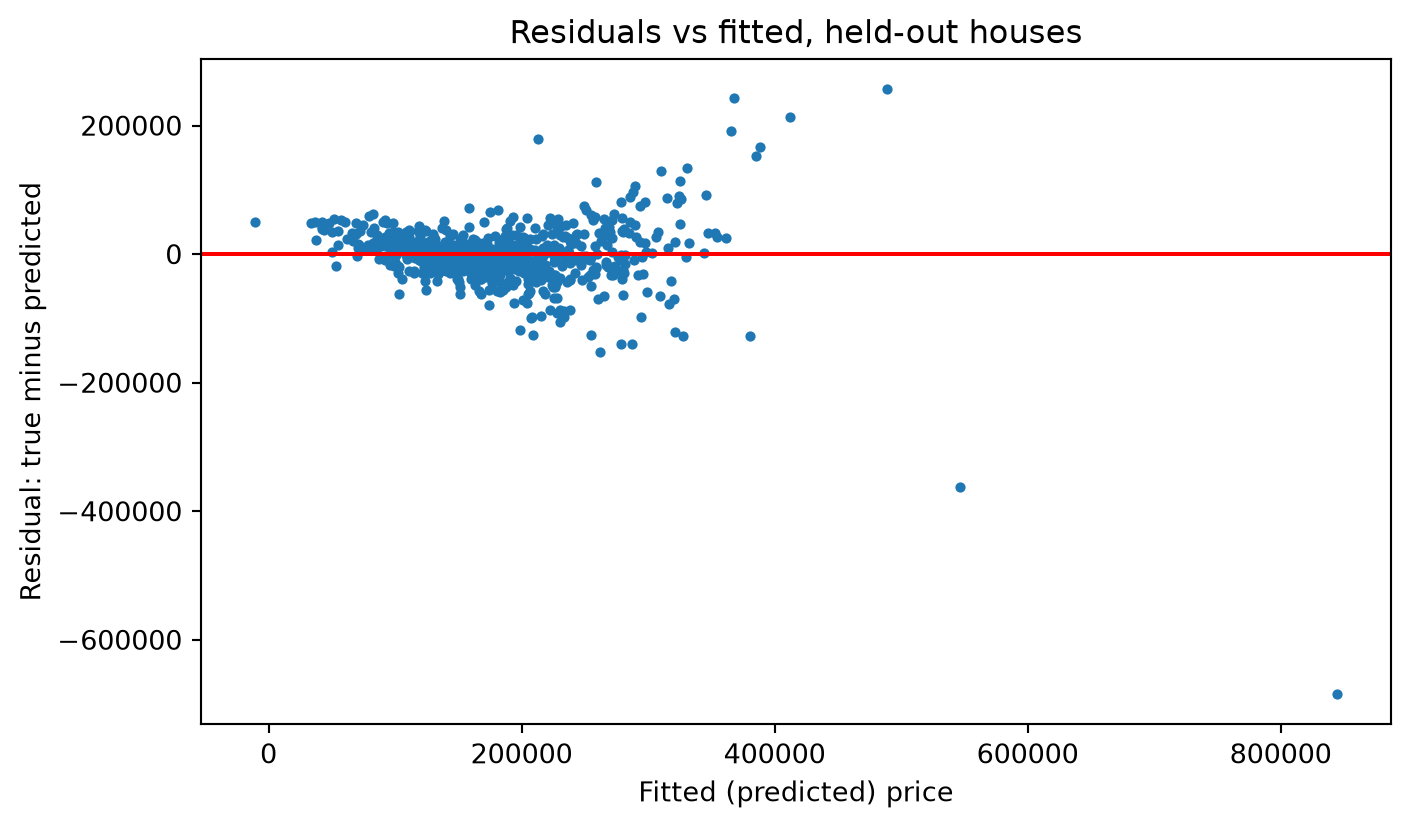
\(R^2\) compresses the fit into one number; the residuals \(\mathbf{e} = \mathbf{y} - \hat{\mathbf{y}}\) show where the model is wrong. Plot them against the fitted values, again for the held-out houses:
Code
resid_test = y_test - y_oos_predict

fig, ax = plt.subplots(figsize=(8, 4.5))
ax.scatter(y_oos_predict, resid_test, s=8)
ax.axhline(0, color='r')
ax.set_xlabel('Fitted (predicted) price')
ax.set_ylabel('Residual: true minus predicted')
ax.set_title('Residuals vs fitted, held-out houses')
plt.show()

Ames: look at the residuals, cont.

  • Fan: spread grows with the fitted price (heteroscedasticity)
  • Two far-right points: huge houses, partial sales – high leverage
  • Fix for the fan: model \(\log(\text{SalePrice})\)
  • Check every time: a bow, a fan, a lone high-leverage point

Recap

  • Linear models are a powerful tool for prediction and inference
  • Least squares is a projection: the normal equations say the residual is orthogonal to every column of \(X\)
  • The \(R^2\) statistic provides a simple measure of fit; judge it on held-out data
  • Coefficients are conditional slopes, each read with the other features held fixed
  • Plot the residuals against the fitted values: a bow, a fan or a lone high-leverage point says the model is wrong in a way \(R^2\) cannot show
  • Careful use of the model is required to avoid overfitting