import importlib
import importlib.util
import os
import subprocess
import sys

os.environ["HF_HUB_DISABLE_PROGRESS_BARS"] = "1"
os.environ["HF_HUB_VERBOSITY"] = "error"
os.environ["TRANSFORMERS_VERBOSITY"] = "error"
os.environ["TOKENIZERS_PARALLELISM"] = "false"

if importlib.util.find_spec("bertopic") is None:
    subprocess.run([sys.executable, "-m", "pip", "install", "-q", "bertopic"], check=True)

import spacy

if not spacy.util.is_package("en_core_web_sm"):
    subprocess.run([sys.executable, "-m", "spacy", "download", "en_core_web_sm"], check=True)
    importlib.invalidate_caches()

import nltk

NLTK_DATA = {
    "tokenizers/punkt_tab": "punkt_tab",
    "corpora/stopwords": "stopwords",
    "corpora/wordnet": "wordnet",
    "taggers/averaged_perceptron_tagger_eng": "averaged_perceptron_tagger_eng",
    "sentiment/vader_lexicon": "vader_lexicon",
}
for path, package in NLTK_DATA.items():
    try:
        nltk.data.find(path)
    except LookupError:
        try:
            nltk.data.find(path + ".zip")
        except LookupError:
            nltk.download(package, quiet=True)

from transformers.utils import logging as hf_logging
hf_logging.disable_progress_bar()NLP Packages Overview

This document provides an overview of Python packages for Natural Language Processing: NLTK, spaCy and BERTopic with runnable examples, plus a short pointer to LangChain. It is the code companion to Lecture 18: Natural Language Processing.
Setup
The cell below installs what a fresh Colab session is missing (BERTopic and spaCy’s small English model) and downloads the NLTK data used further down. On a machine where everything is already installed it does nothing.
NLTK (Natural Language Toolkit)
Overview
NLTK is one of the oldest and most comprehensive Python libraries for NLP, originally created for teaching and research.
Key Features:
- Extensive collection of text processing tools
- Access to over 50 corpora and lexical resources (WordNet, TreeBank)
- Text classification, tokenization, stemming, tagging, parsing
- Educational focus with extensive documentation
Best For:
- Learning NLP concepts
- Prototyping and research
- Working with linguistic data structures
- Academic projects and teaching
Limitations:
- Slower than modern alternatives
- Less suited for production environments
- Requires more manual pipeline construction
NLTK Example: Basic Text Processing
Code
from nltk.tokenize import word_tokenize, sent_tokenize
from nltk.corpus import stopwords
from nltk.stem import PorterStemmer, WordNetLemmatizer

text = """Natural language processing (NLP) is a fascinating field.
It enables computers to understand and process human language.
NLTK provides excellent tools for learning NLP concepts."""

# Tokenization
sentences = sent_tokenize(text)
words = word_tokenize(text)

print("Sentences:", len(sentences))
print("Words:", len(words))
print("\nFirst sentence tokens:", word_tokenize(sentences[0]))

# Remove stopwords
stop_words = set(stopwords.words('english'))
filtered_words = [w for w in words if w.lower() not in stop_words and w.isalpha()]
print("\nFiltered words:", filtered_words)

# Stemming vs Lemmatization
stemmer = PorterStemmer()
lemmatizer = WordNetLemmatizer()

words_to_process = ['running', 'runs', 'ran', 'easily', 'fairly']
print("\n{:<15} {:<15} {:<15}".format("Original", "Stemmed", "Lemmatized"))
print("-" * 45)
for word in words_to_process:
    stemmed = stemmer.stem(word)
    lemmatized = lemmatizer.lemmatize(word, pos='v')  # v = verb
    print("{:<15} {:<15} {:<15}".format(word, stemmed, lemmatized))
Sentences: 3
Words: 30
First sentence tokens: ['Natural', 'language', 'processing', '(', 'NLP', ')', 'is', 'a', 'fascinating', 'field', '.']
Filtered words: ['Natural', 'language', 'processing', 'NLP', 'fascinating', 'field', 'enables', 'computers', 'understand', 'process', 'human', 'language', 'NLTK', 'provides', 'excellent', 'tools', 'learning', 'NLP', 'concepts']
Original Stemmed Lemmatized
---------------------------------------------
running run run
runs run run
ran ran run
easily easili easily
fairly fairli fairly NLTK Example: Part-of-Speech Tagging
Code
from nltk import pos_tag

sentence = "The quick brown fox jumps over the lazy dog"
tokens = word_tokenize(sentence)
pos_tags = pos_tag(tokens)

print("Part-of-Speech Tags:")
for word, tag in pos_tags:
    print(f"  {word:10} -> {tag}")
Part-of-Speech Tags:
The -> DT
quick -> JJ
brown -> NN
fox -> NN
jumps -> VBZ
over -> IN
the -> DT
lazy -> JJ
dog -> NNNLTK Example: Sentiment Analysis
Code
from nltk.sentiment import SentimentIntensityAnalyzer

sia = SentimentIntensityAnalyzer()

texts = [
    "I absolutely love this product! It's amazing!",
    "This is terrible. I hate it.",
    "It's okay, nothing special.",
    "The weather is nice today."
]

print("Sentiment Analysis Results:")
print("-" * 60)
for text in texts:
    scores = sia.polarity_scores(text)
    print(f"Text: {text}")
    print(f"  Negative: {scores['neg']:.3f}, Neutral: {scores['neu']:.3f}, Positive: {scores['pos']:.3f}")
    print(f"  Compound Score: {scores['compound']:.3f}\n")
Sentiment Analysis Results:
------------------------------------------------------------
Text: I absolutely love this product! It's amazing!
Negative: 0.000, Neutral: 0.311, Positive: 0.689
Compound Score: 0.871
Text: This is terrible. I hate it.
Negative: 0.694, Neutral: 0.306, Positive: 0.000
Compound Score: -0.778
Text: It's okay, nothing special.
Negative: 0.367, Neutral: 0.325, Positive: 0.309
Compound Score: -0.092
Text: The weather is nice today.
Negative: 0.000, Neutral: 0.588, Positive: 0.412
Compound Score: 0.421
spaCy
Overview
spaCy is a modern, industrial-strength NLP library designed for production use.
Key Features:
- Fast and efficient (Cython-optimized)
- Tokenization for 75+ languages, trained pipelines for about 25
- Built-in support for NER, POS tagging, dependency parsing
- Easy integration with deep learning frameworks (PyTorch, TensorFlow)
- Beautiful visualization tools (displaCy)
Best For:
- Production NLP pipelines
- Real-time processing
- Named Entity Recognition
- Document similarity and classification
- Information extraction at scale
Limitations:
- Less flexible than NLTK for research
- Fewer resources for learning basic concepts
- Model-dependent (needs pre-trained models)
spaCy: Setup and Models
You need to download the trained pipeline you want to use (the Setup cell above does this for the small one):
pip install spacy
python -m spacy download en_core_web_sm  # Small model
Available English pipelines:
en_core_web_sm: Small (~12 MB) - fast, good accuracy, no word vectorsen_core_web_md: Medium (~40 MB) - word vectors includeden_core_web_lg: Large (~400 MB) - best accuracy, full vectors
spaCy Example: Basic Text Analysis
Code
nlp = spacy.load("en_core_web_sm")

text = """Apple Inc. is planning to open a new store in San Francisco next month.
The CEO, Tim Cook, announced this during a press conference."""

doc = nlp(text)

# Tokenization and linguistic features
print("Tokens and their attributes:")
print("{:<15} {:<10} {:<10} {:<10}".format("Token", "Lemma", "POS", "Is Stop?"))
print("-" * 50)
for token in doc[:10]:  # First 10 tokens
    print("{:<15} {:<10} {:<10} {:<10}".format(
        token.text,
        token.lemma_,
        token.pos_,
        str(token.is_stop)
    ))
Tokens and their attributes:
Token Lemma POS Is Stop?
--------------------------------------------------
Apple Apple PROPN False
Inc. Inc. PROPN False
is be AUX True
planning plan VERB False
to to PART True
open open VERB False
a a DET True
new new ADJ False
store store NOUN False
in in ADP True spaCy Example: Named Entity Recognition
from spacy import displacy

text = ("Apple Inc. was founded by Steve Jobs in Cupertino, California, in 1976. "
        "It reported revenue of $391 billion in fiscal 2024.")
doc = nlp(text)

print("Entities found:")
for ent in doc.ents:
    print(f"  {ent.text:15} -> {ent.label_:8} ({spacy.explain(ent.label_)})")

displacy.render(doc, style="ent", jupyter=True)
Entities found:
Apple Inc. -> ORG (Companies, agencies, institutions, etc.)
Steve Jobs -> PERSON (People, including fictional)
Cupertino -> GPE (Countries, cities, states)
California -> GPE (Countries, cities, states)
1976 -> DATE (Absolute or relative dates or periods)
$391 billion -> MONEY (Monetary values, including unit)
fiscal 2024 -> DATE (Absolute or relative dates or periods)
Apple Inc.
ORG
was founded by
Steve Jobs
PERSON
in
Cupertino
GPE
,
California
GPE
, in
1976
DATE
. It reported revenue of
$391 billion
MONEY
in
fiscal 2024
DATE
.
spaCy NER: Entity Attributes
# Character offsets of each entity in the original text
for ent in doc.ents:
    print(f"{ent.text:15} | Label: {ent.label_:8} | Start: {ent.start_char:3} | End: {ent.end_char:3}")

# Filter by entity type
orgs = [ent.text for ent in doc.ents if ent.label_ == "ORG"]
print(f"\nOrganizations: {orgs}")

# The sentence each entity belongs to
for sent in doc.sents:
    print(f"\n{sent.text}\n  entities: {[ent.text for ent in sent.ents]}")
Apple Inc. | Label: ORG | Start: 0 | End: 10
Steve Jobs | Label: PERSON | Start: 26 | End: 36
Cupertino | Label: GPE | Start: 40 | End: 49
California | Label: GPE | Start: 51 | End: 61
1976 | Label: DATE | Start: 66 | End: 70
$391 billion | Label: MONEY | Start: 95 | End: 107
fiscal 2024 | Label: DATE | Start: 111 | End: 122
Organizations: ['Apple Inc.']
Apple Inc. was founded by Steve Jobs in Cupertino, California, in 1976.
entities: ['Apple Inc.', 'Steve Jobs', 'Cupertino', 'California', '1976']
It reported revenue of $391 billion in fiscal 2024.
entities: ['$391 billion', 'fiscal 2024']spaCy Pipeline Architecture
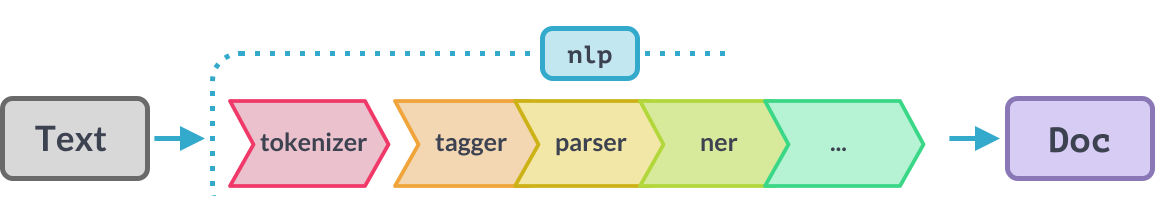
print("Pipeline components:", nlp.pipe_names)Pipeline components: ['tok2vec', 'tagger', 'parser', 'attribute_ruler', 'lemmatizer', 'ner']Processing steps (the tokenizer runs first and is not listed):
- tok2vec: Convert tokens to vectors shared by later components
- tagger: Part-of-speech tagging
- parser: Dependency parsing
- attribute_ruler: Rule-based token attributes
- lemmatizer: Word lemmatization
- ner: Named entity recognition
See spaCy 101 to dive deeper.
spaCy Example: Dependency Parsing
Code
sentence = nlp("The quick brown fox jumps over the lazy dog")

print("\nDependency Parse:")
print("{:<10} {:<10} {:<10} {:<10}".format("Token", "Dependency", "Head", "Children"))
print("-" * 50)
for token in sentence:
    children = ", ".join([child.text for child in token.children])
    print("{:<10} {:<10} {:<10} {:<10}".format(
        token.text,
        token.dep_,
        token.head.text,
        children if children else "-"
    ))

# Visualize dependency tree
displacy.render(
    sentence,
    style="dep",
    jupyter=True,
    options={
        "compact": False,
        "color": "blue",
        "bg": "#fff",
        "distance": 120,
        "width": 700,
        "height": 300,
        "font": "10px Arial"    # Reduce font size
    }
)
Dependency Parse:
Token      Dependency Head       Children
--------------------------------------------------
The        det        fox        -
quick      amod       fox        -
brown      amod       fox        -
fox        nsubj      jumps      The, quick, brown
jumps      ROOT       jumps      fox, over
over       prep       jumps      dog
the        det        dog        -
lazy       amod       dog        -
dog pobj over the, lazy spaCy Example: Document Similarity
en_core_web_sm has no word vectors, so spaCy falls back on its context-sensitive tensors and warns (W007) that the result may be poor. The cell suppresses that repeated warning; the output shows why it is issued: king comes out closer to apple than to queen. Install en_core_web_md or en_core_web_lg for meaningful similarities.
Code
import warnings

warnings.filterwarnings("ignore", message=r"\[W007\]")

doc1 = nlp("I love programming in Python")
doc2 = nlp("I enjoy coding with Python")
doc3 = nlp("The weather is nice today")

print("\nDocument Similarity (using word vectors):")
print(f"doc1 <-> doc2: {doc1.similarity(doc2):.3f}")
print(f"doc1 <-> doc3: {doc1.similarity(doc3):.3f}")
print(f"doc2 <-> doc3: {doc2.similarity(doc3):.3f}")

# Word similarity
word1 = nlp("king")
word2 = nlp("queen")
word3 = nlp("apple")

print("\nWord Similarity:")
print(f"king <-> queen: {word1.similarity(word2):.3f}")
print(f"king <-> apple: {word1.similarity(word3):.3f}")
Document Similarity (using word vectors):
doc1 <-> doc2: 0.839
doc1 <-> doc3: 0.271
doc2 <-> doc3: 0.322

Word Similarity:
king <-> queen: 0.422
king <-> apple: 0.690
BERTopic
Overview
BERTopic (Grootendorst 2022) is a topic modeling technique that leverages transformer-based embeddings. The pipeline is explained in Lecture 18: embed → UMAP → HDBSCAN → c-TF-IDF.
Key Features:
- Uses sentence-transformer embeddings for semantic understanding
- HDBSCAN chooses the number of topics, given
min_topic_size - UMAP for dimensionality reduction
- Class-based TF-IDF (c-TF-IDF) for topic representation
- Interactive visualizations
Best For:
- Topic discovery in document collections
- Short text analysis (tweets, reviews, articles)
- Dynamic topic modeling over time (with real timestamps)
- Modern alternative to LDA
Limitations:
- Computationally expensive (needs embeddings)
- Requires more memory than classical methods
- Slower than LDA for very large corpora
- GPU recommended for large datasets
- Topic words need stop-word handling, like any TF-IDF
BERTopic: Installation
pip install bertopic # brings sentence-transformers, umap-learn and hdbscanBERTopic Example: Fit on Three Newsgroups
The corpus is the one used in Lecture 18 and in Lecture 4. Three choices make the result readable and reproducible:
- the embeddings are computed once and passed in, so refitting is cheap;
- UMAP gets a
random_state, so the topics are the same on every run; - the c-TF-IDF step gets a stop-word list, so topics are not named
the_of_to.
from bertopic import BERTopic
from sentence_transformers import SentenceTransformer
from sklearn.datasets import fetch_20newsgroups
from sklearn.feature_extraction.text import CountVectorizer
from umap import UMAP

categories = ['comp.os.ms-windows.misc', 'sci.space', 'rec.sport.baseball']
posts = fetch_20newsgroups(subset='all', categories=categories,
                           remove=('headers', 'footers', 'quotes'))['data']
posts = [p for p in posts if len(p.split()) >= 5]       # drop empty posts

embedder = SentenceTransformer("all-MiniLM-L6-v2")
embeddings = embedder.encode(posts, show_progress_bar=False)

topic_model = BERTopic(
    embedding_model=embedder,
    umap_model=UMAP(n_neighbors=15, n_components=5, min_dist=0.0,
                    metric="cosine", random_state=42),
    vectorizer_model=CountVectorizer(stop_words="english",
                                     token_pattern=r"(?u)\b[a-zA-Z]{3,15}\b"),
    min_topic_size=10)
topics, probs = topic_model.fit_transform(posts, embeddings)

print(f"Posts: {len(posts)}")
print(f"Topics found: {len(set(topics) - {-1})}")
print(f"Outlier posts (topic -1): {topics.count(-1)}")
Posts: 2823
Topics found: 21
Outlier posts (topic -1): 285BERTopic Example: Reduce and Explore Topics
21 topics is more than we can read. reduce_topics merges the most similar ones; nr_topics counts the outlier topic −1 as one of them.
topic_model.reduce_topics(posts, nr_topics=10)
topics = topic_model.topics_

topic_info = topic_model.get_topic_info()
print(topic_info[['Topic', 'Count', 'Name']].to_string(index=False))
Topic Count Name
-1 285 -1_windows_file_dos_files
0 993 0_space_nasa_earth_launch
1 925 1_year_game_team_games
2 351 2_windows_file_dos_use
3 123 3_card_mouse_drivers_driver
4 54 4_printer_print_deskjet_canon
5 39 5_font_fonts_characters_truetype
6 21 6_sound_midi_driver_play
7 20 7_max_bhj_giz_bxn
8 12 8_disks_mac_read_disk# Top words (with c-TF-IDF scores) for the six largest topics
for topic_id in topic_info.Topic[topic_info.Topic != -1][:6]:
words = topic_model.get_topic(topic_id)
print(f"Topic {topic_id}: " + ", ".join(f"{w}({s:.2f})" for w, s in words[:6]))
# Representative posts for one topic
print("\nRepresentative posts for topic 0:")
for i, post in enumerate(topic_model.get_representative_docs(0)[:2], 1):
print(f"{i}. {' '.join(post.split())[:100]}...")Topic 0: space(0.04), nasa(0.02), earth(0.02), launch(0.02), orbit(0.01), shuttle(0.01)
Topic 1: year(0.03), game(0.03), team(0.02), games(0.02), baseball(0.02), don(0.02)
Topic 2: windows(0.07), file(0.04), dos(0.04), use(0.03), files(0.02), run(0.02)
Topic 3: card(0.11), mouse(0.09), drivers(0.07), driver(0.07), video(0.06), windows(0.05)
Topic 4: printer(0.14), print(0.10), deskjet(0.07), canon(0.06), ink(0.05), printers(0.05)
Topic 5: font(0.22), fonts(0.21), characters(0.09), truetype(0.09), character(0.08), windows(0.08)
Representative posts for topic 0:
1. THE ELECTRONIC JOURNAL OF THE ASTRONOMICAL SOCIETY OF THE ATLANTIC Volume 4, Number 9 - April 1993 #...
2. Archive-name: space/intro Last-modified: $Date: 93/04/01 14:39:10 $ FREQUENTLY ASKED QUESTIONS ON SC...BERTopic: Visualize Topics
Code
fig = topic_model.visualize_topics()
fig.update_layout(width=700, height=500)
fig.show()
BERTopic: Visualize Topic Hierarchy
Code
fig = topic_model.visualize_hierarchy()
fig.update_layout(width=800, height=500)
fig.show()
BERTopic: Visualize Topic Bar Chart
Code
fig = topic_model.visualize_barchart(top_n_topics=8)
fig.show()
BERTopic: Visualize Topic Heatmap
Code
fig = topic_model.visualize_heatmap()
fig.update_layout(width=700, height=600)
fig.show()
BERTopic: Find Topics for a Query
query = "space exploration and satellites"
similar_topics, similarity = topic_model.find_topics(query, top_n=3)

print(f"Topics similar to '{query}':")
for topic_id, score in zip(similar_topics, similarity):
    words = ', '.join(word for word, _ in topic_model.get_topic(topic_id)[:5])
    print(f"  Topic {topic_id} (similarity: {score:.3f}): {words}")
Topics similar to 'space exploration and satellites':
Topic 0 (similarity: 0.593): space, nasa, earth, launch, orbit
Topic 2 (similarity: 0.072): windows, file, dos, use, files
Topic 7 (similarity: 0.069): max, bhj, giz, bxn, chzBERTopic: Topics Over Time
Warning
Synthetic timestamps — API demo only. The newsgroup posts carry no dates once the headers are removed, so the dates below are invented (one per day, in corpus order). The plot shows how to call the API, not how any topic evolved.
Code
import pandas as pd

timestamps = pd.date_range('2020-01-01', periods=len(posts), freq='D')

topics_over_time = topic_model.topics_over_time(posts, timestamps, nr_bins=10)

fig = topic_model.visualize_topics_over_time(topics_over_time, top_n_topics=5)
fig.update_layout(width=900)
fig.show()
With real timestamps the same two calls track, for example, news trends over months or how the subjects of product reviews change.
BERTopic: Customization
Every step of the pipeline can be replaced:
from hdbscan import HDBSCAN

topic_model = BERTopic(
    embedding_model=SentenceTransformer("all-mpnet-base-v2"),   # step 1
    umap_model=UMAP(n_neighbors=15, n_components=5, min_dist=0.0,
                    random_state=42),                           # step 2
    hdbscan_model=HDBSCAN(min_cluster_size=15, min_samples=10), # step 3
    vectorizer_model=CountVectorizer(stop_words="english"),     # step 4
)
BERTopic: Practical Tips
Best practices:
- Compute embeddings once and pass them to
fit_transform - Seed UMAP (
random_state) if you need the same topics twice - Always give the vectorizer a stop-word list
- For short texts, use smaller
min_topic_size(5-10) - For long documents, increase
min_topic_size(20-50) - Read the topics: some will be junk (encoded files, signatures)
- Save models for reuse:
topic_model.save("my_model")
Common issues:
- Too many outliers? Lower
min_topic_size, or usereduce_outliers - Too many small topics? Increase
min_topic_sizeor callreduce_topics - Slow performance? Use a smaller embedding model
- Poor topics? Try a different embedding model or more documents
LangChain
Overview
LangChain (Chase 2022) is a framework for building applications on top of large language models. It gives one interface to many model providers and chains prompts, model calls, document retrieval and tool calls into one pipeline. A typical use is retrieval-augmented generation: find the documents nearest a question (cosine similarity on embeddings, as in Lecture 18) and pass them to the model with the question.
It needs an API key for a hosted model (or a local model), so the sketch below is not run here:
from langchain.chat_models import init_chat_model

# Substitute a provider (e.g. "openai", "anthropic", "ollama") and one of its model names
model = init_chat_model("<model-name>", model_provider="<provider>")
reply = model.invoke("Summarize TF-IDF in one sentence.")
print(reply.content)
Package Comparison
Quick Comparison Table
| Feature | NLTK | spaCy | BERTopic |
|---|---|---|---|
| Primary Use | Education, Research | Production NLP | Topic Modeling |
| Speed | Slow | Fast | Moderate |
| Ease of Use | Moderate | Easy | Easy |
| Pre-trained Models | Limited | Excellent | Uses transformer embeddings |
| Customization | High | Moderate | Moderate |
| Memory Usage | Low | Low-Moderate | High |
| Best For | Learning, Prototyping | NER, Pipelines, Real-time | Topic Discovery |
| Visualization | Limited | Excellent (displaCy) | Excellent (interactive) |
| GPU Support | No | Yes (for training) | Recommended |
| Community | Large, Academic | Large, Industry | Growing |
When to Use Each Package
Use NLTK when:
- Learning NLP concepts
- Need access to linguistic resources (WordNet, TreeBank)
- Working on academic research
- Prototyping ideas
- Need maximum flexibility
Use spaCy when:
- Building production systems
- Need fast, accurate NER
- Processing large volumes of text
- Want beautiful visualizations
- Need dependency parsing
- Building information extraction pipelines
Use BERTopic when:
- Discovering topics in document collections
- Working with short texts (tweets, reviews)
- You can choose a sensible minimum topic size
- Have access to GPU resources
- Analyzing topic evolution over time (with real timestamps)
Combining Packages
These packages can be used together effectively:
Code
# Example: NLTK stop words, spaCy for NER and lemmatization

documents = [
    "Apple Inc. announced new products in Cupertino yesterday.",
    "Google is developing AI technology in Mountain View.",
    "Microsoft released a new version of Windows in Seattle."
]

# Step 1: Use NLTK for basic preprocessing
stop_words = set(stopwords.words('english'))

# Step 2: Use spaCy for NER and lemmatization
processed_docs = []
for doc in documents:
    spacy_doc = nlp(doc)

    # Extract entities
    entities = [(ent.text, ent.label_) for ent in spacy_doc.ents]
    print(f"\nDocument: {doc}")
    print(f"Entities: {entities}")

    # Lemmatize and remove stopwords
    lemmatized = [token.lemma_ for token in spacy_doc
                  if token.text.lower() not in stop_words and not token.is_punct]
    processed_docs.append(" ".join(lemmatized))

print("\n\nProcessed documents:")
for i, doc in enumerate(processed_docs, 1):
    print(f"{i}. {doc}")
Document: Apple Inc. announced new products in Cupertino yesterday.
Entities: [('Apple Inc.', 'ORG'), ('Cupertino', 'GPE'), ('yesterday', 'DATE')]

Document: Google is developing AI technology in Mountain View.
Entities: [('Google', 'ORG'), ('AI', 'ORG'), ('Mountain View', 'GPE')]

Document: Microsoft released a new version of Windows in Seattle.
Entities: [('Microsoft', 'ORG'), ('Windows', 'NORP'), ('Seattle', 'GPE')]


Processed documents:
1. Apple Inc. announce new product Cupertino yesterday
2. Google develop AI technology Mountain View
3. Microsoft release new version Windows Seattle
The processed documents could then go to BERTopic, which needs far more than three documents to find topics.
Summary
- NLTK: Comprehensive, educational, flexible but slower
- spaCy: Fast, production-ready, excellent for NER and pipelines
- BERTopic: Modern topic modeling with transformer embeddings
- LangChain: Glue for applications built on large language models
Choose based on your specific needs: learning (NLTK), production (spaCy), or topic discovery (BERTopic). Often, combining these tools yields the best results!
References
Chase, Harrison. 2022. LangChain. Https://github.com/langchain-ai/langchain.
Grootendorst, Maarten. 2022. “BERTopic: Neural Topic Modeling with a Class-Based TF-IDF Procedure.” arXiv Preprint arXiv:2203.05794. https://arxiv.org/abs/2203.05794.