Recap: Recommender Systems
DS701 Session 22 — Wed Nov 18, 2026


Today’s plan
- 5 min — knowledge-check review
- 20 min — highlights and Q&A (answer or pass — answering always earns credit)
- 50 min — case study: recommendations for a library’s e-media platform
- wrap-up and cold-call check-ins
Knowledge-Check Review
KC 1: Predicting a missing rating
In item–item collaborative filtering, how is a missing rating \(\hat r_{ui}\) predicted? Name the two ingredients (what is compared to what, and how the pieces are combined), and say why the ratings matrix being 99.97% empty is the central difficulty rather than a detail.
KC 2: “Something like an SVD”
The lecture said we want “something like an SVD” of the ratings matrix but cannot use the SVD algorithm directly, and instead minimises \(\Vert (R - UV^T)_S \Vert^2 + \lambda(\Vert U\Vert^2 + \Vert V\Vert^2)\) by alternating least squares. Explain (a) why the SVD cannot be applied as-is, (b) what the subscript \(S\) does to the objective, and (c) why holding \(U\) fixed turns the problem into one you already know how to solve.
KC 3: The latent space, again
In Session 14 you took the SVD of a small ratings matrix with planted taste factors and saw users and items land in a shared latent space. Connect that to today: what does a row of \(U\) and a row of \(V\) mean* in the recommender’s factorization, how is a rating formed from them, and what can this shared space do that item–item CF cannot? Then name one situation in which neither CF nor MF has anything to say.*
Highlights
The user–item matrix — and the hole in it
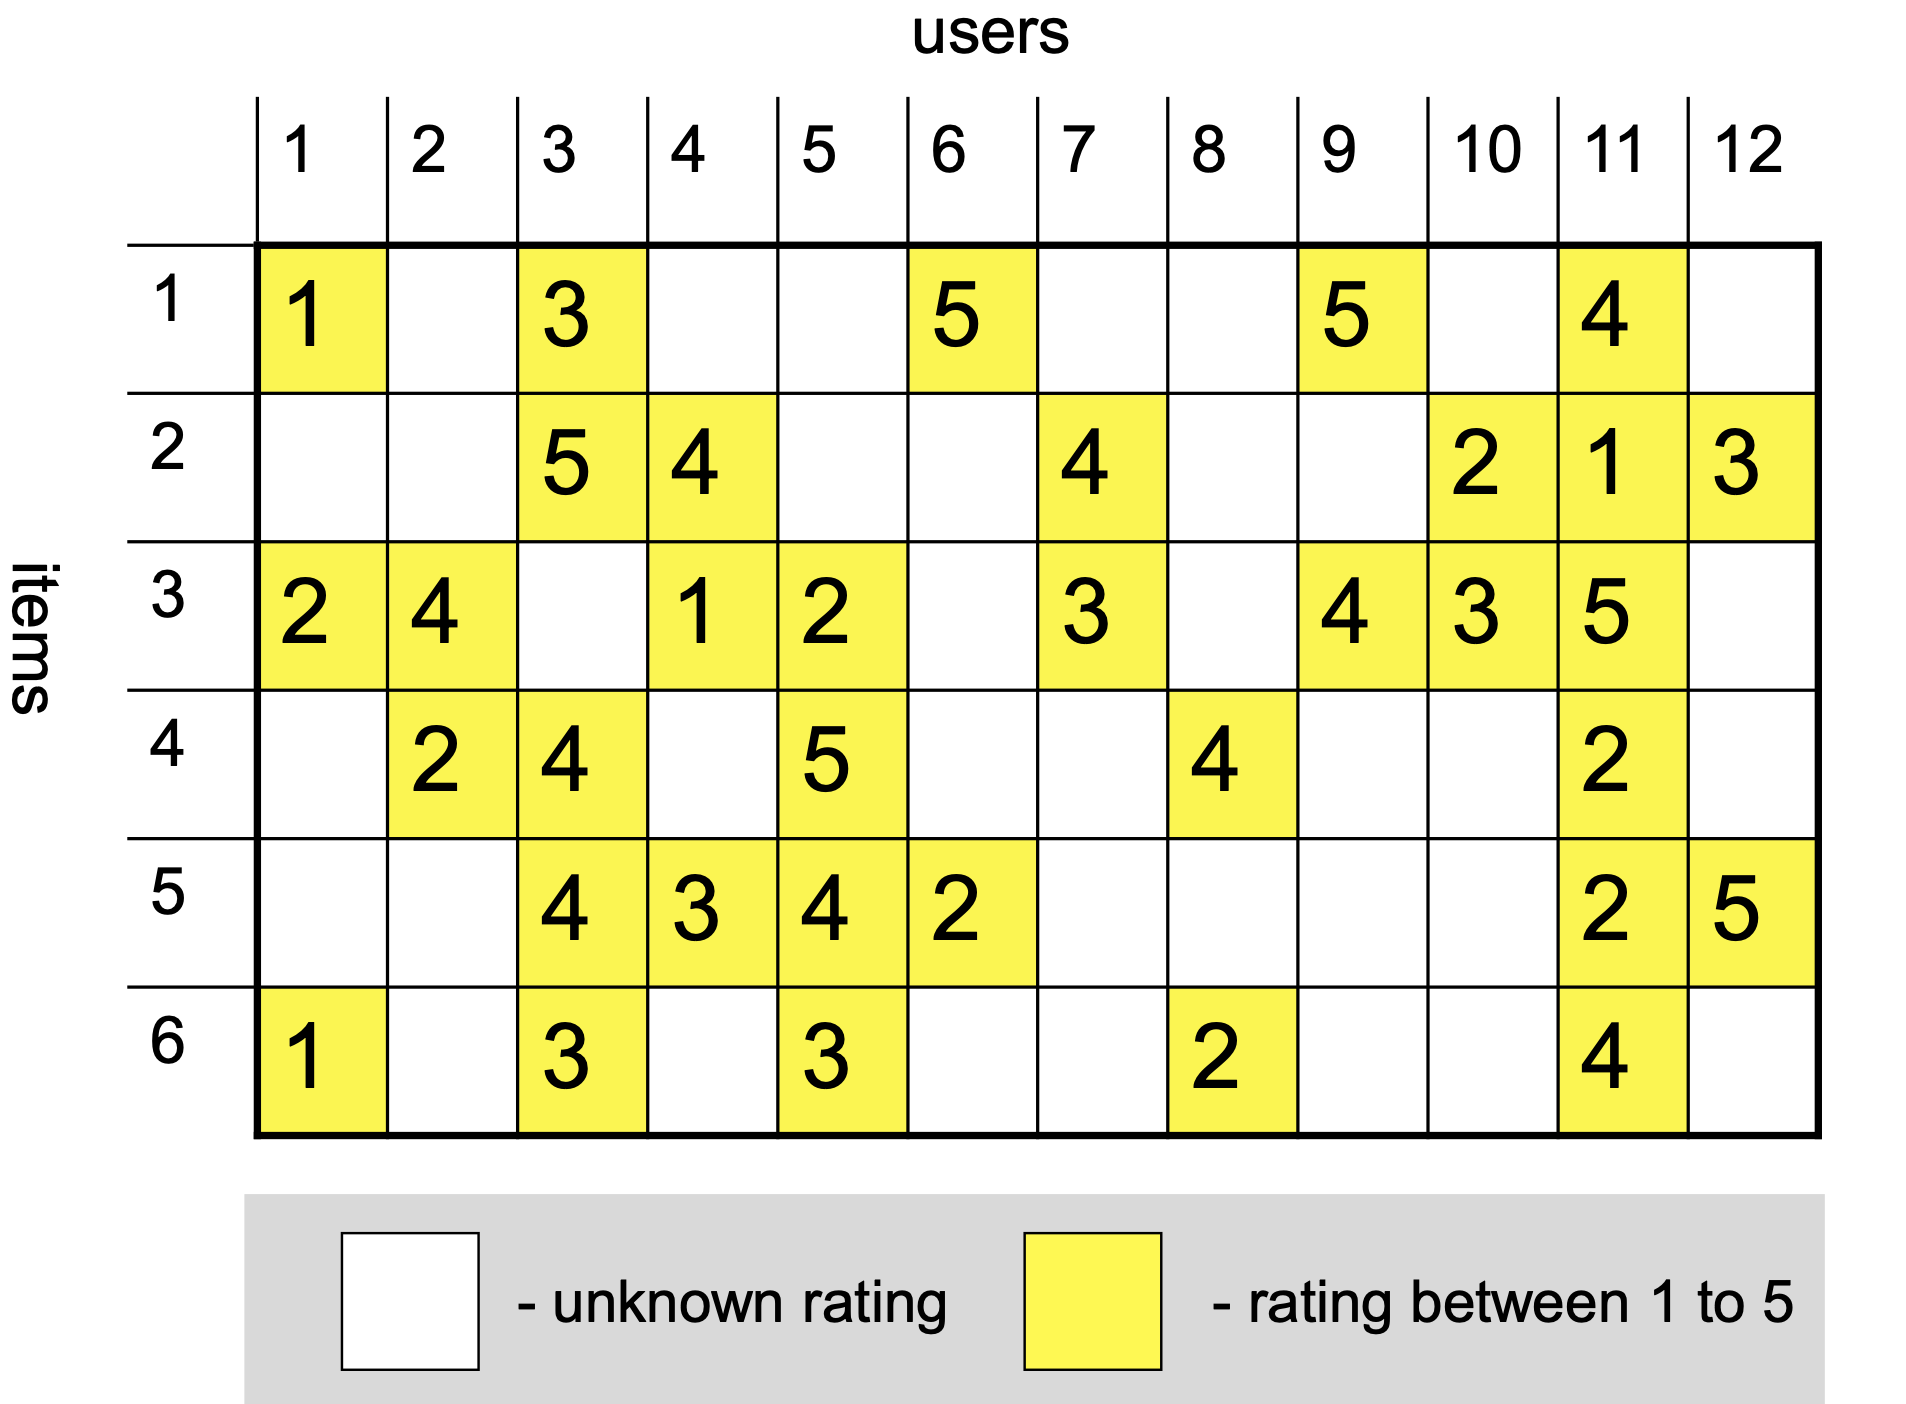
- Rows are items, columns are users, entries are ratings \(r_{ui}\) — the same object as the bipartite graph of known ratings.
- Amazon movies: 1.7M reviews, ~50K movies, ~124K users → 99.97% empty. \[\text{sparsity} = \frac{\#\text{ reviews}}{\#\text{ users}\times\#\text{ items}}\]
- And it is skewed: the average movie has 34 reviews, but most have far fewer (power law) — for most rows there is almost nothing to go on.
- Goal: predict the blanks; score with RMSE on held-out known ratings. Baseline to beat: the global mean \(\mu\).
Collaborative filtering: neighbours in rating space
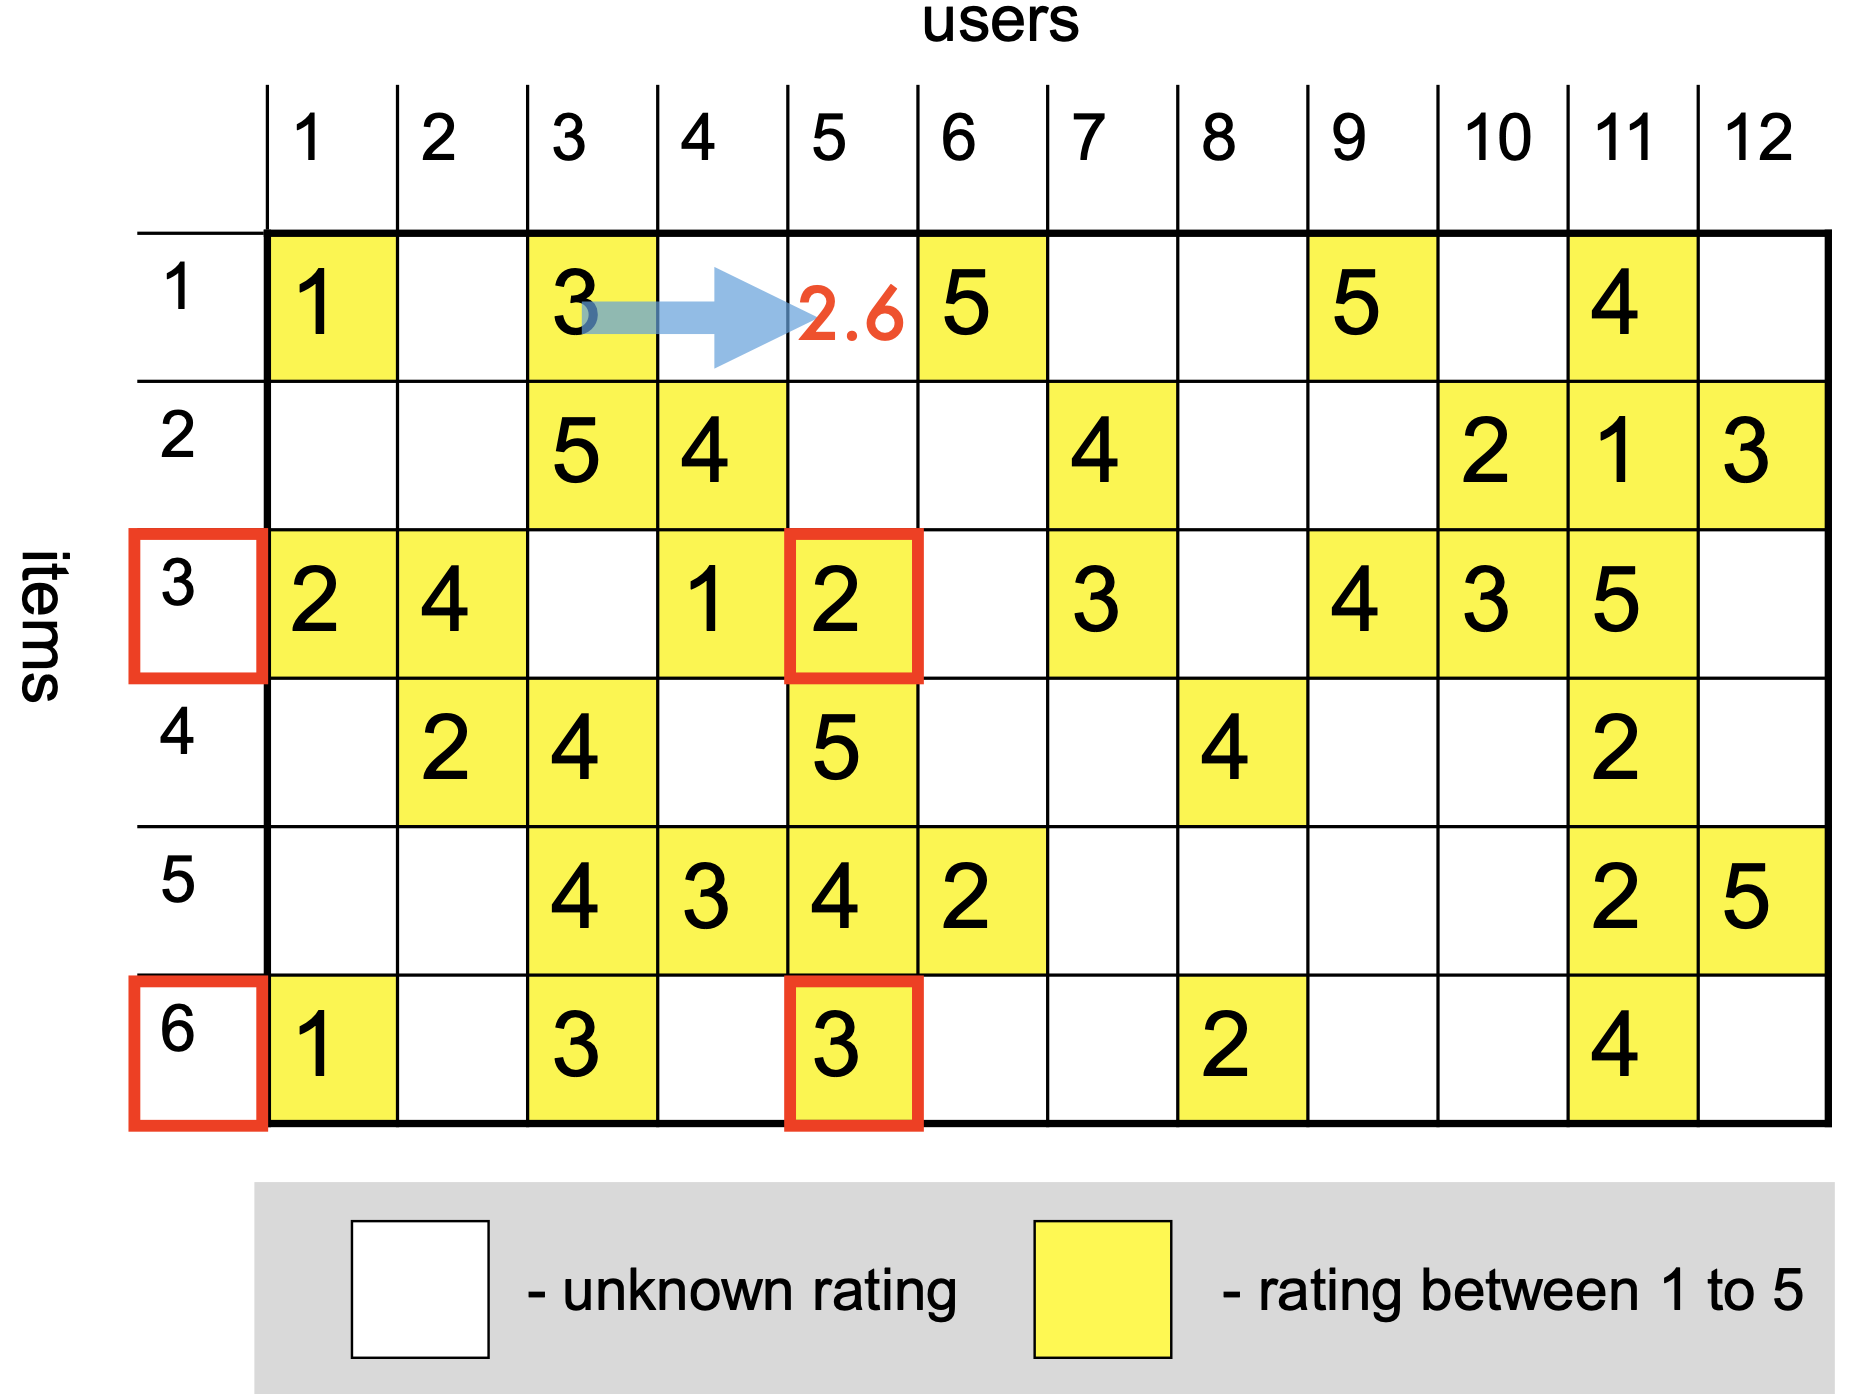
Item–item: to guess \(r_{ui}\), look at items like \(i\) that \(u\) has rated, and average.
\[ \hat r_{ui} = \frac{\sum_{j \in n_k(i,u)} s_{ij}\, r_{uj}}{\sum_{j \in n_k(i,u)} s_{ij}} \qquad \frac{0.84\cdot 2 + 1.0\cdot 3}{0.84 + 1.0} = 2.54 \]
- \(n_k(i,u)\): the \(k\) nearest neighbours of \(i\) among the items \(u\) rated — it is \(k\)-NN.
- \(s_{ij}\): correlation of the two items’ rating rows, over the users who rated both (\(s_{13} = 0.84\), \(s_{16} = 1.0\) in the example).
- User–user is the mirror image. Rule of thumb: compare along the short side — few items, many users → item–item (Netflix; Amazon too): a smaller similarity table, each entry backed by more co-raters.
Correct for bias first
Some users rate everything high; some items are simply loved. Left in, that noise masquerades as similarity.
\[ b_{ui} = \mu + \alpha_u + \beta_i \qquad\text{(global mean, user offset, item offset)} \]
Compute similarity on the residuals \(r_{ui} - b_{ui}\), and add the bias back when predicting:
\[ \hat r_{ui} = b_{ui} + \frac{\sum_{j \in n_k(i,u)} s_{ij}\,(r_{uj} - b_{uj})}{\sum_{j \in n_k(i,u)} s_{ij}} \]
Two practicalities: estimate \(\mu, \alpha, \beta\) by alternating regularised least squares over the observed entries (fix two, solve the third); and keep only positively similar neighbours, or the denominator can collapse.
CF’s report card: no training, easy to update, explainable (“because you liked Blade Runner”) — but accuracy is limited and neighbour search does not scale.
Matrix factorization: low rank = latent tastes
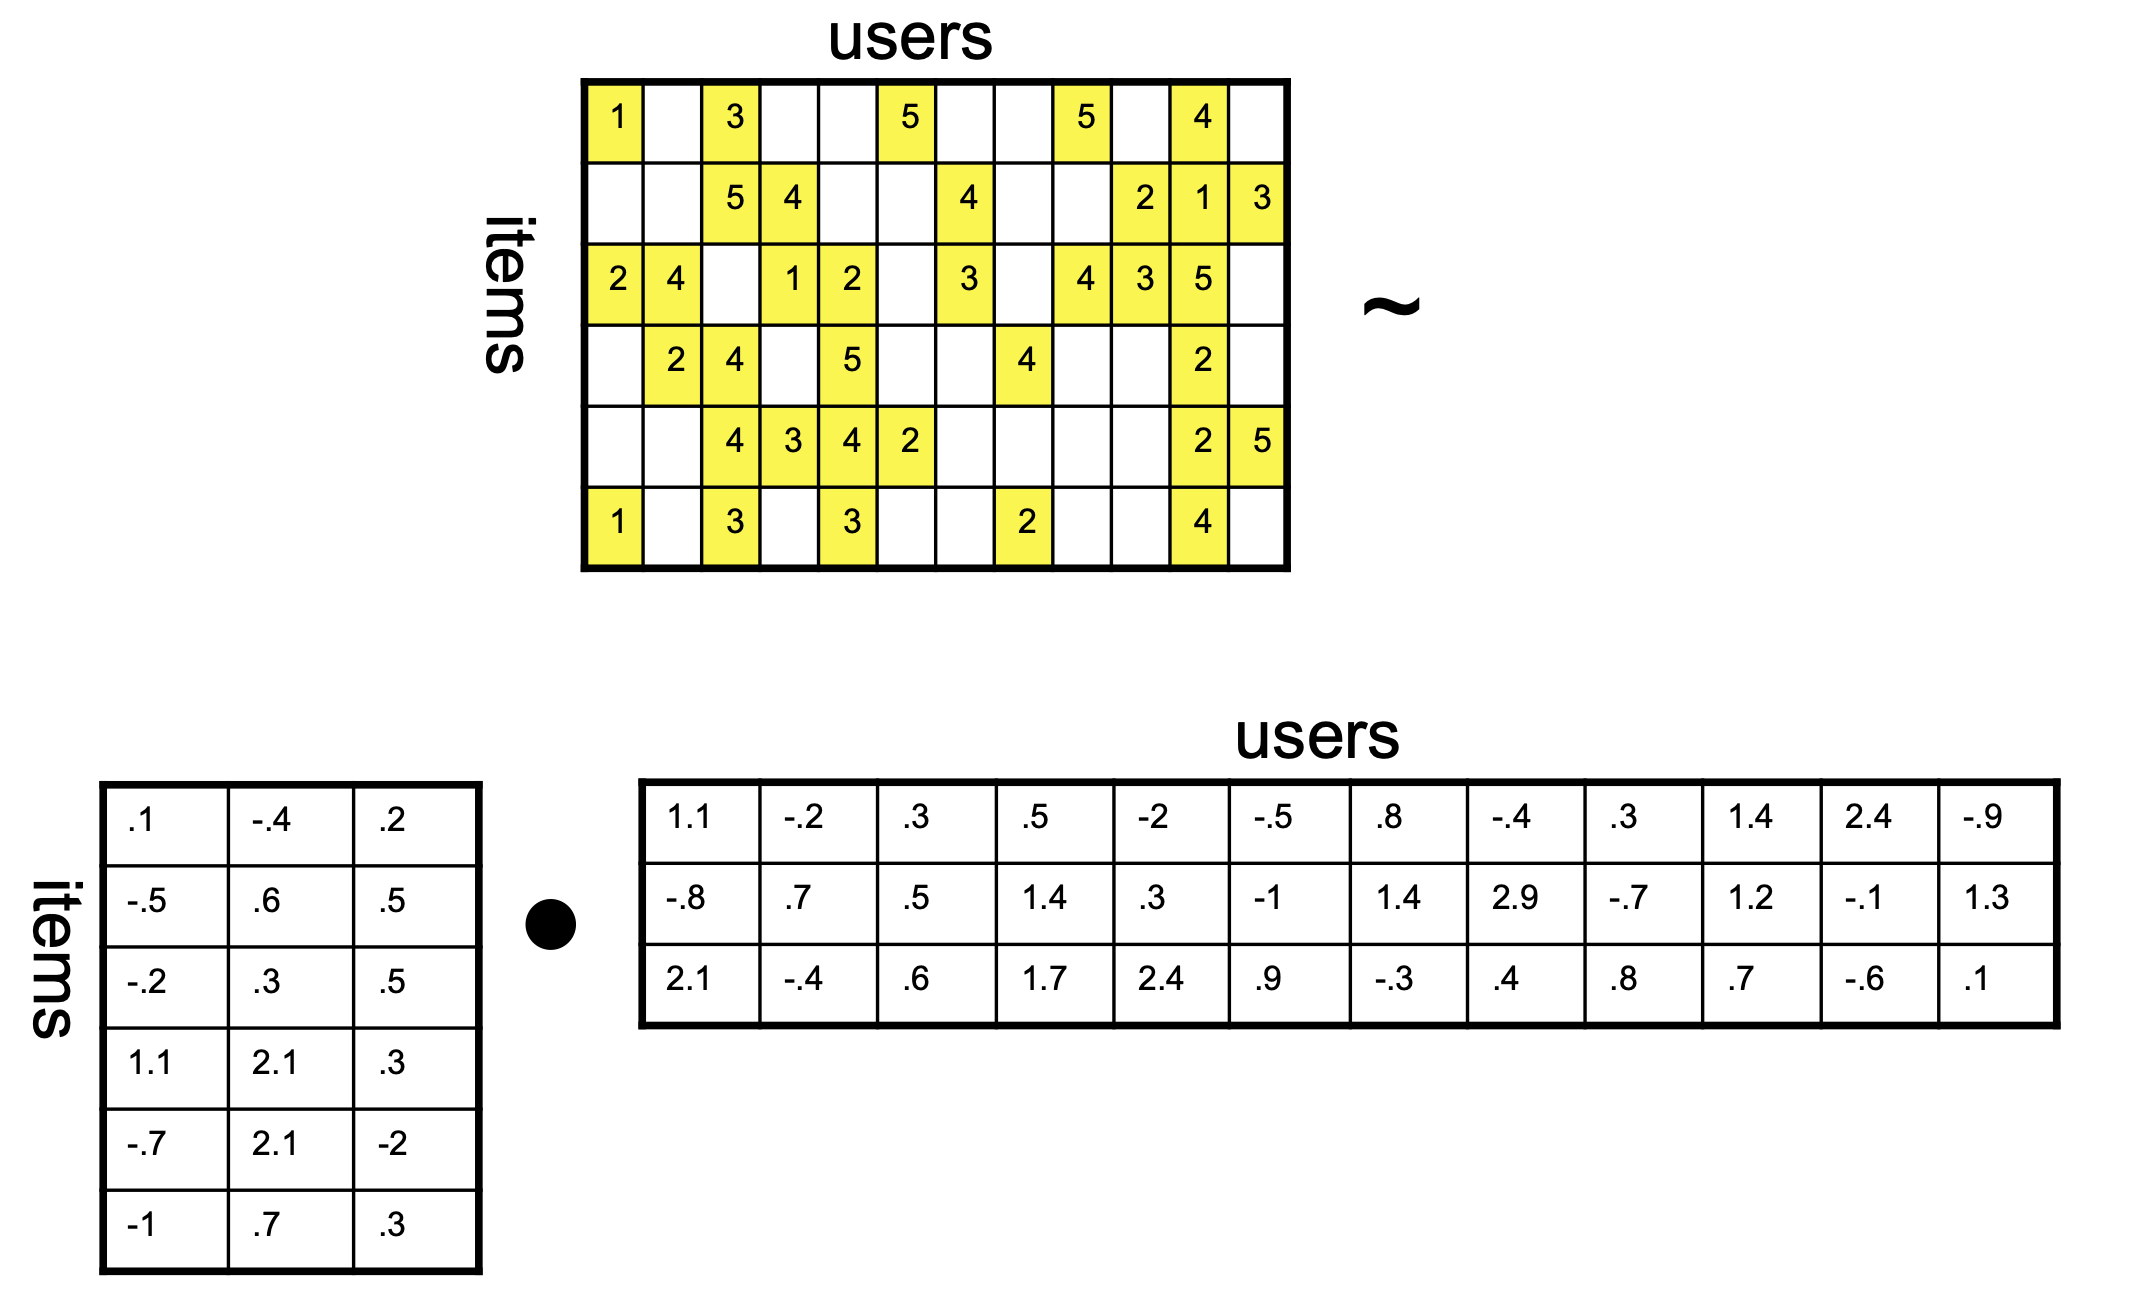
CF uses item similarity or user similarity. MF puts both in one latent space:
- \(R \approx UV^T\) — one \(k\)-vector per user, \(\mathbf u_u\), and per item, \(\mathbf v_i\); predicted rating \(= \mathbf u_u^\top \mathbf v_i\).
- This is Session 14’s SVD picture — rank \(k\) latent factors — but the matrix is partially observed, so we fit only where we can see: \[ \min_{U,V}\ \Vert (R - UV^T)_S\Vert^2 + \lambda\big(\Vert U\Vert^2 + \Vert V\Vert^2\big) \]
- \(\lambda\): ridge penalty — rank 20 with \(\lambda = 1\) reached training RMSE 0.31 but held-out 1.29, worse than the global mean.
ALS in one slide
Biconvex, not jointly convex: fix one factor and the objective is convex in the other.
- Hold \(U\) fixed → solve for \(V\)
- Hold \(V\) fixed → solve for \(U\)
- Not converged? Go to 1.
Each half-step is a ridge regression per row, restricted to that row’s observed entries:
\[ \mathbf u_u = \big(V_{J_u}^\top V_{J_u} + \lambda I\big)^{-1} V_{J_u}^\top \mathbf r_{u, J_u} \]
\(J_u\) = the items user \(u\) rated, \(V_{J_u}\) = their factor rows. Every step lowers the objective → converges.
MF in practice (lifted from Recommender Systems II):
- \(U\) and \(V\) are embedding tables: a lookup from an ID to a learned vector; the dot product is the interaction. Modern deep recommenders (DLRM) keep exactly this core and add MLPs around it.
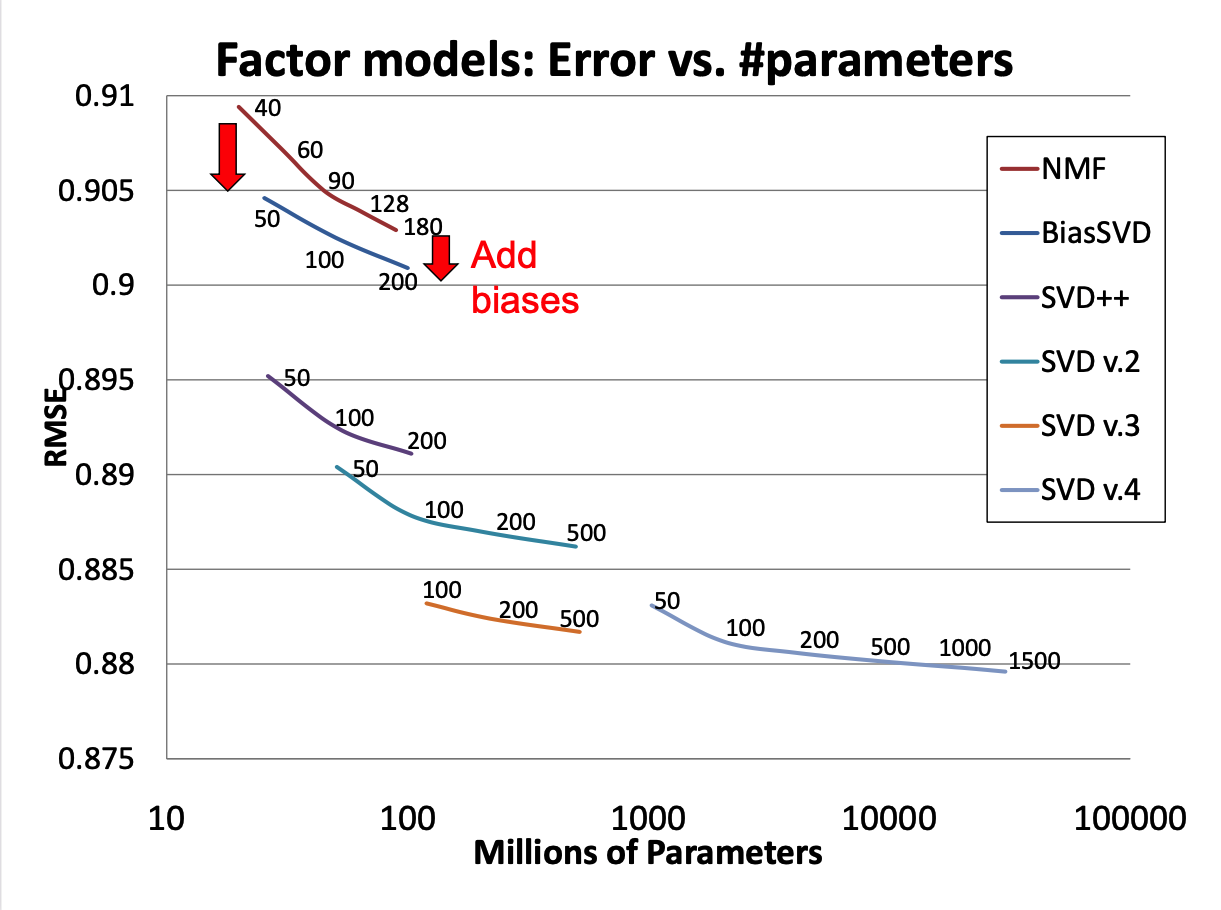
- Netflix Prize: plain MF → + biases (\(\mu + \alpha_u + \beta_i + \mathbf u^\top\mathbf v\)) → + who rated what → + time-varying biases; RMSE 0.951 → 0.856. The time and implicit terms break the two-block structure ⇒ stochastic gradient descent, not ALS.
Evaluate on ratings you hid
- Honest protocol: hold out a random slice of the known ratings, fit on the rest, predict the slice, RMSE there.
- The lecture’s dense block: global mean 1.17; rank 20, \(\lambda = 1\): 0.31 training but 1.29 held-out; rank 5, \(\lambda = 10\): 1.01. Training RMSE keeps falling with \(k\); held-out RMSE tells you when you are memorising.
- Still optimistic: the densest block, and ratings are missing not at random. The product needs a good top-\(k\) list (precision@\(k\)), and offline ≠ online (A/B test).
- Today: 70% missing, 100 ratings held out, and you will read all three numbers off — global mean, item–item CF, MF.
The standing limitation: cold start
Everything on the previous slides needs a history.
- New user, zero ratings: CF has no co-ratings and no neighbours; in MF only \(\lambda\Vert\mathbf u_{\text{new}}\Vert^2\) involves her, so \(\mathbf u_{\text{new}} = \mathbf 0\) and \(\hat r = 0\) — or \(\mu + \beta_i\) with biases: the same list for everyone.
- New item, zero ratings: the mirror image — no similarity, factor \(\mathbf 0\), never recommended.
- Real systems are hybrids: onboarding ratings, content features and popularity priors bridge the gap until collaborative signal arrives.
Today’s report-out: a patron who has borrowed nothing — what each method predicts for her, why, and the cheapest thing that beats the global mean.
In-Class Activity
Activity — Case Study 19: Recommendations for a Public Library’s E-Media Platform
Goal: a public library’s e-media platform wants a “patrons who borrowed this also borrowed…” panel and a plan for brand-new patrons, but its borrowing records cannot leave the library — so you work on a simulator built to the library’s stated shape (80 patrons, 36 titles, planted genres and biases, 70% missing), where the truth is known. Part 1 measures the sparsity and scores two baselines on held-out ratings; Part 2 builds item–item CF by hand (adjusted-cosine similarity, \(k\)-NN prediction) so a librarian can see one recommendation computed; Part 3 implements ALS for matrix factorization, checks it beats the baselines on held-out ratings, and checks the learned factors recover the genres. The report-out answers the library’s second question from the lecture’s cold-start section: what to show a patron who has borrowed nothing.
- Work in groups of 2–3. Open your section’s notebook — the service differs.
- Parts marked (autograded) are submitted to Gradescope; the rest is participation.
- Staff will circulate — be ready to explain any part of your work.
- Dependencies:
numpy,pandas,matplotlib,scikit-learn.

The activity notebook goes live on the day of the lecture. Colab is optional — you can also open it on GitHub and run it locally.
Going deeper
Full lecture notes: Recommender Systems
- Reviews are Sparse and Sparseness is Skewed — the Amazon numbers
- Item–Item CF — the worked \(\hat r_{u=5,\,i=1}\) example, step by step
- Similarity — Pearson on the common support; binary data
- Improving CF in the presence of bias — the bias model and how it is estimated
- Negative Similarity Scores? and Common Solutions
- Matrix Factorization and Solving Matrix Factorization — the objective and ALS
- The ALS Update — the per-row ridge formula and a rank-1 example
- ALS in Practice and Held-Out Evaluation — the dense-block run against the global mean
- Cold Start — what neither method can do, and the hybrid fixes
- Assessing Matrix Factorization — the Netflix Prize improvements
- The latent-space picture from Session 14: Low Rank Defines Latent Factors
- Where the factors go next: Recommender Systems II — embeddings and DLRM